Terminal-Bench 4.0: The $234 Solved Task
Terminal-Bench 4.0 now runs 35 entries and Claude Opus 5.5 leads at 64.85 percent. Derived cost per solved task runs from 1 to 234 dollars, a 175x spread.
The Terminal-Bench 4.0 leaderboard publishes something most benchmark boards leave out: the dollar cost of each run. Thirty-five agent-and-model pairs, 330 trials each, and a full-precision total spend next to almost every score.
Divide that spend by the number of trials the model actually solved and you get the number that decides procurement: the price of one solved task. On the current board it runs from $1.34 to $234.24. The most expensive entry also sits second from the bottom on accuracy.
What Terminal-Bench 4.0 actually changed
Terminal-Bench grades an agent on hard command-line work by running a verification script against the machine’s end state. The agent either reached the required state or it did not, so a convincing transcript earns nothing.
Version 4.0, announced on August 28, 2026 by Ryan Marten, is a maintenance release rather than a new benchmark:
- Resources were calibrated. Every task now carries a flat 8-hour agent timeout, replacing per-task budgets. The announcement reports that frontier models now never or rarely time out.
- Eight tasks were removed: two for saturation, two for refusals, two because public solutions exist, and two for unresolved quality or platform-compatibility problems. A task counted as saturated when every class in every family of the latest model generation solved it five times out of five.
- Nineteen tasks were fixed, updating instructions, environments and verifiers.
That leaves 66 tasks, which is 74 minus 8. Two independent checks confirm it: the v4.0.0 release tree on GitHub contains exactly 66 task directories, and every leaderboard row reports 330 trials, which is 66 tasks at five trials each.
The cost of one solved task
Here is the full board, with the derived column on the right.
| Model | Agent | Accuracy | ±95% CI | Solved | Total cost | Cost per solved task |
|---|---|---|---|---|---|---|
| Claude Opus 5.5 (max) | Claude Code | 64.85% | 3.11 | 214/330 | $4,718.65 | $22.05 |
| Claude Sonnet 5.5 (max) | Claude Code | 61.82% | 2.94 | 204/330 | $7,333.64 | $35.95 |
| GPT-6.1 Sol (max) | Codex | 58.18% | 3.11 | 192/330 | $634.24 | $3.30 |
| GPT-6 Astra (max) | Codex | 58.18% | 2.79 | 192/330 | $3,267.18 | $17.02 |
| GPT-6 Astra (high) | Codex | 57.88% | 2.97 | 191/330 | $2,269.42 | $11.88 |
| GPT-6 Astra (xhigh) | Codex | 57.88% | 2.72 | 191/330 | $2,350.51 | $12.31 |
| Claude Fable 5.1 (xhigh) | Claude Code | 57.88% | 3.36 | 191/330 | $4,872.04 | $25.51 |
| Claude Fable 5.1 (max) | Claude Code | 57.88% | 3.76 | 191/330 | $6,243.50 | $32.69 |
| Claude Fable 5.1 (high) | Claude Code | 54.55% | 3.44 | 180/330 | $3,985.38 | $22.14 |
| GPT-6 Astra (medium) | Codex | 54.24% | 2.66 | 179/330 | $1,914.80 | $10.70 |
| Claude Fable 5.1 (medium) | Claude Code | 53.94% | 3.39 | 178/330 | $2,832.90 | $15.92 |
| Claude Opus 5 (xhigh) | Claude Code | 53.94% | 3.17 | 178/330 | $6,086.22 | $34.19 |
| Claude Opus 5 (max) | Claude Code | 51.82% | 3.39 | 171/330 | $5,969.11 | $34.91 |
| GPT-6 Astra (low) | Codex | 50.61% | 2.75 | 167/330 | $1,557.30 | $9.33 |
| Claude Opus 5 (high) | Claude Code | 50.30% | 3.73 | 166/330 | $4,662.27 | $28.09 |
| GPT-6 Sol (max) | Codex | 49.39% | 3.23 | 163/330 | $1,451.32 | $8.90 |
| Claude Opus 5 (medium) | Claude Code | 44.85% | 3.83 | 148/330 | $3,191.59 | $21.56 |
| Claude Fable 5 (max) | Claude Code | 44.55% | 3.85 | 147/330 | $7,265.01 | $49.42 |
| Claude Fable 5.1 (low) | Claude Code | 43.33% | 3.61 | 143/330 | $2,358.72 | $16.49 |
| GLM-5.3 (max) | Claude Code | 41.82% | 3.23 | 138/330 | $2,727.63 | $19.77 |
| Grok 4.7 (xhigh) | Grok Build | 37.58% | 3.54 | 124/330 | $3,683.29 | $29.70 |
| GPT-5.6 Sol (max) | Codex | 37.27% | 3.78 | 123/330 | $2,541.70 | $20.66 |
| GLM-5.3-Flash | Claude Code | 35.76% | 3.54 | 118/330 | $2,883.11 | $24.43 |
| Claude Opus 5 (low) | Claude Code | 34.85% | 3.94 | 115/330 | $2,393.88 | $20.82 |
| Qwen3.8-Max-0902 (max) | Claude Code | 26.97% | 3.78 | 89/330 | $4,635.67 | $52.09 |
| Claude Opus 4.8 (max) | Claude Code | 23.64% | 3.56 | 78/330 | $6,481.26 | $83.09 |
| GPT-5.6 Terra (max) | Codex | 21.52% | 3.25 | 71/330 | $1,733.52 | $24.42 |
| Grok 4.6 (high) | Grok Build | 20.30% | 3.09 | 67/330 | $3,591.58 | $53.61 |
| Gemini 3.8 Flash (high) | mini-SWE-agent | 19.09% | 3.36 | 63/330 | $1,828.77 | $29.03 |
| GPT-5.6 Luna (max) | Codex | 17.27% | 2.85 | 57/330 | $346.67 | $6.08 |
| GPT-6 Luna (max) | Codex | 16.36% | 2.72 | 54/330 | $72.14 | $1.34 |
| Muse Spark 1.3 (xhigh) | Muse Code | 14.55% | 2.94 | 48/330 | not reported | n/a |
| Grok 4.5 (high) | Grok Build | 12.42% | 2.62 | 41/330 | $2,094.11 | $51.08 |
| Claude Sonnet 5 (max) | Claude Code | 12.42% | 3.06 | 41/330 | $9,603.86 | $234.24 |
| Gemini 3.7 Flash (high) | mini-SWE-agent | 11.21% | 2.45 | 37/330 | $1,261.87 | $34.10 |
The accuracy, confidence interval, solved count and total cost are published by Terminal-Bench. The final column is this site’s arithmetic: published cost divided by published solved trials. It is not a figure tbench.ai reports, and it is not a price anyone quoted.
Two rows carry caveats. Grok 4.7 is still marked partial by the board itself, at 324 of its 330 trials, so its accuracy is computed over a denominator six trials larger than the run that produced it. The effect is small and downward. Muse Spark 1.3, run in Meta’s Muse Code harness, is listed with a total cost of $0.00 against 9.0 billion tokens. That is a missing figure, not a free run, so the row gets no cost per solved task here and is left off the chart below. Two more of the new rows, GLM-5.3-Flash and Qwen3.8-Max-0902, both run in Claude Code, publish run costs several times what their makers’ list rates imply for the token counts shown: roughly $126 and $1,500 at list, against $2,883.11 and $4,635.67 published. The board does not say which endpoint or rate it billed, so read those two cost-per-solved figures as the board’s arithmetic, not as what the model costs at list price.
Did the vendor numbers hold up?
Five models that were missing at the September update are now on the board, and for the first time the launch claims can be checked against an independent run.
- Claude Opus 5.5 reported 66.4% on Terminal-Bench 4.0 at launch. The board measures 64.85%, 1.55 points lower and inside its own 3.11-point interval. The vendor figure holds up, and the model takes the top of the board by 6.7 points over GPT-6 Astra.
- Claude Sonnet 5.5 reported 70.6%, which would have put it above Opus 5.5. The board measures 61.82%, 8.8 points short and well outside its 2.94-point interval. It is still second on the board, and a vendor table can differ from an independent run in effort, harness and resources, so the gap is not evidence of error. It is the number a buyer can reproduce.
- GPT-6 Sol and GPT-6 Luna, released on September 22 at half the GPT-5.6 rates, landed at 49.39% for $8.90 per solved task and 16.36% for $1.34. Sol gains 12.1 points on the GPT-5.6 Sol row and costs $11.76 less per solved task. Luna costs less than a quarter of GPT-5.6 Luna’s $6.08 for 0.9 points less accuracy, inside the interval.
- GPT-6.1 Sol, the DevDay upgrade a week later at the same $2 and $10 per million tokens, then matched GPT-6 Astra’s best score at 58.18% for $3.30 per solved task.
The board is the reason the cost column exists; a vendor figure cannot substitute for one, because it comes with no published run cost to divide.
It is also not a per-task price you would pay in production. A benchmark trial is a worst-case unit of work: a hard, unfamiliar task with an 8-hour budget and no repository context the model has seen before. Read the column as a ratio between models measured under identical conditions, not as a quote.
| Model | Accuracy | Cost per solved task | On the cost-efficiency frontier |
|---|---|---|---|
| Opus 5.5 (max) | 64.85% | $22.05 | Yes |
| Sonnet 5.5 (max) | 61.82% | $35.95 | No |
| GPT-6.1 Sol (max) | 58.18% | $3.30 | Yes |
| Astra (max) | 58.18% | $17.02 | No |
| Astra (high) | 57.88% | $11.88 | No |
| Astra (xhigh) | 57.88% | $12.31 | No |
| Fable 5.1 (xhigh) | 57.88% | $25.51 | No |
| Fable 5.1 (max) | 57.88% | $32.69 | No |
| Fable 5.1 (high) | 54.55% | $22.14 | No |
| Astra (medium) | 54.24% | $10.70 | No |
| Fable 5.1 (medium) | 53.94% | $15.92 | No |
| Opus 5 (xhigh) | 53.94% | $34.19 | No |
| Opus 5 (max) | 51.82% | $34.91 | No |
| Astra (low) | 50.61% | $9.33 | No |
| Opus 5 (high) | 50.3% | $28.09 | No |
| GPT-6 Sol (max) | 49.39% | $8.90 | No |
| Opus 5 (medium) | 44.85% | $21.56 | No |
| Fable 5 (max) | 44.55% | $49.42 | No |
| Fable 5.1 (low) | 43.33% | $16.49 | No |
| GLM-5.3 (max) | 41.82% | $19.77 | No |
| Grok 4.7 (xhigh) | 37.58% | $29.70 | No |
| GPT-5.6 Sol (max) | 37.27% | $20.66 | No |
| GLM-5.3-Flash | 35.76% | $24.43 | No |
| Opus 5 (low) | 34.85% | $20.82 | No |
| Qwen3.8-Max-0902 (max) | 26.97% | $52.09 | No |
| Opus 4.8 (max) | 23.64% | $83.09 | No |
| GPT-5.6 Terra (max) | 21.52% | $24.42 | No |
| Grok 4.6 (high) | 20.3% | $53.61 | No |
| Gemini 3.8 Flash (high) | 19.09% | $29.03 | No |
| GPT-5.6 Luna (max) | 17.27% | $6.08 | No |
| GPT-6 Luna (max) | 16.36% | $1.34 | Yes |
| Grok 4.5 (high) | 12.42% | $51.08 | No |
| Sonnet 5 (max) | 12.42% | $234.24 | No |
| Gemini 3.7 Flash (high) | 11.21% | $34.10 | No |
Three entries are non-dominated, meaning nothing else on the board beats them on both axes at once:
- GPT-6 Luna at $1.34 is the new floor. It solves only 16.36%, but nothing cheaper exists, and its whole 330-trial run cost $72.14.
- GPT-6.1 Sol at $3.30 solves 58.18%, the same score as GPT-6 Astra at max, for about a fifth of Astra’s $17.02. It is the value pick by a wide margin.
- Claude Opus 5.5 at $22.05 is the capability pick: the most accurate entry on the board, and cheaper per solved task than the Opus 5 it replaced ($34.91) by 37%.
The September frontier had five points, and four of them were GPT-6 Astra at different reasoning-effort settings. All four are now dominated by GPT-6.1 Sol, which ties or beats every Astra setting on accuracy at a lower cost per solved task than any of them. GPT-5.6 Luna lost the floor to its successor.
The other 31 costed entries are strictly dominated. Claude Sonnet 5.5 is the notable case: it is second on accuracy at 61.82%, but Opus 5.5 is both more accurate and $13.90 cheaper per solved task, because Sonnet 5.5 used 19.4 billion tokens to Opus 5.5’s 8.0 billion. Claude Opus 4.8 remains the clearest generational case: it costs 2.4 times what Opus 5 costs per solved task and solves 93 fewer trials.
Sonnet 5 is the most expensive way to fail
The single most striking row is Claude Sonnet 5. It posted the largest absolute bill on the board, $9,603.86, which is $3,634 more than Opus 5 spent. It solved 41 of 330 trials to Opus 5’s 171. Per solved task it costs $234.24, which is 6.7 times Opus 5 and 175 times GPT-6 Luna.
The cheaper model produced the larger invoice, and a quarter of the results.
The mechanism is in the announcement, and it is token consumption rather than the per-token rate. Terminal-Bench reports Sonnet 5 burning 21.6 billion tokens on its leaderboard run against 6.5 billion for Opus 5, hitting both timeouts and output-token-exceeded errors, and struggling to stay inside its maximum output length. The operators note they did not enable the 128k max-output-tokens setting, which might have helped, and that they saw large variance in how long Sonnet 5 took.
This is the failure mode covered in why cheaper AI models cost more, and it is the reason a per-million-token rate card cannot rank models on its own. A weaker model on a long-horizon task does not fail quickly and cheaply. It retries, re-reads, and re-plans until the budget runs out, and the meter runs the entire time. Sonnet 5 is the joint cheapest model per token in the Anthropic column of this board, sharing the $2 and $10 rate card with Sonnet 5.5, and the most expensive per unit of finished work by a factor of six.
The same logic cuts the other way for GPT-5.6 Luna, which consumed 11.6 billion tokens, more than Opus 5, and still billed only $346.67. Cheap tokens plus heavy caching keep a high-volume, low-accuracy run affordable. Volume alone does not predict the bill, and price alone does not predict the bill. Only the product of the two does.
GPT-6 Astra is the same principle read from the opposite end. Astra is the joint most expensive model here per token, at $10 input and $50 output, matching Claude Fable 5.1 exactly. It consumed 1.53 billion tokens at max effort, against 2.75 billion for Fable 5.1, 6.53 billion for Opus 5 and 21.6 billion for Sonnet 5. Per solved task that works out to 8.0 million tokens for Astra against 14.4 million for Fable 5.1, 38.2 million for Opus 5 and 525.9 million for Sonnet 5. A model can charge 2.5 times more per token than its own predecessor and still be cheaper to finish the work with, which is exactly what happened between GPT-5.6 Sol and Astra.
GPT-6.1 Sol then showed the other half of the product. It used 1.46 billion tokens, almost exactly Astra’s count, and solved the same 192 trials, but it charges $2 and $10 per million against Astra’s $10 and $50, with cached input at $0.10. Same token volume, a fifth of the rate, a fifth of the bill: $634.24 against $3,267.18. When two models need the same tokens for the same result, the rate card does decide, which is the one case where it can.
The same name, three different numbers
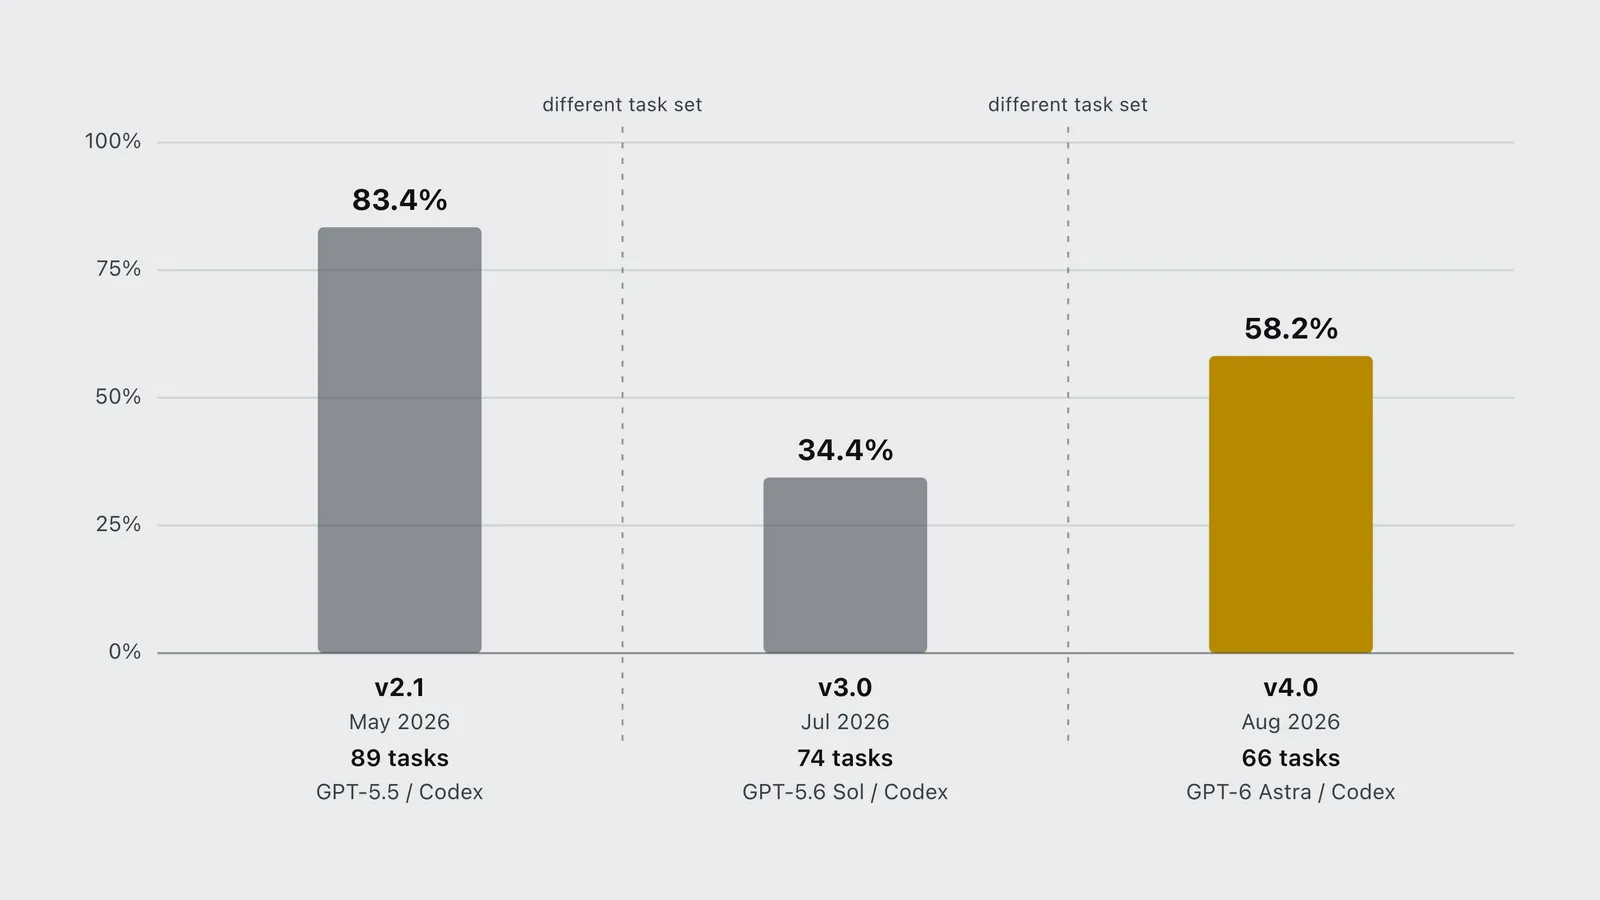
Terminal-Bench has shipped three task sets in four months under one name, and treating their top scores as a trend line would be a mistake. The older boards also keep moving: tbench.ai now serves a re-run board for each version, and on October 20, 2026 the 2.1 board was led by GPT-6 Astra at 87.4% and the 3.0 board by Claude Opus 5 at 42.7%, both above the figures each version launched with.
| Version | Released | Tasks | Top score | Set by |
|---|---|---|---|---|
| v2.1 | May 2026 | 89 | 87.4% | GPT-6 Astra / Codex |
| v3.0 | Jul 2026 | 74 | 42.7% | Opus 5 / mini-SWE-agent |
| v4.0 | Aug 2026 | 66 | 64.85% | Opus 5.5 / Claude Code |
Version 3.0, released on July 30, 2026, was not an edit of 2.1. It was a fresh set of 74 tasks across seven domains, built explicitly because the older tasks had saturated and the leaderboard had compressed into a range too narrow to separate models. At release the top score fell from about 83% to 34.4% because the work got harder, not because the models got worse; the 3.0 board later reached 42.7%, set by Claude Opus 5 in the minimal mini-SWE-agent harness. The same team took the same approach with Harbor-Index, where no agent it tested cleared 30%. Between 3.0 and 4.0 the score then rose to 51.82%, partly because a stronger model arrived and partly because the task set lost eight of its members and every task gained an 8-hour budget. Within 4.0 it has since risen again, to 58.18% in September and 64.85% in October, and that movement is clean: the task set has not changed since August 28, only the models running against it have.
None of this is a defect. It is the maintenance an execution-graded benchmark needs, and Terminal-Bench documents each change in public. But it does mean a launch post citing “Terminal-Bench” with no version attached is quoting a number with no fixed meaning, which is the argument made at length in are AI benchmarks reliable and AI agent benchmarks in 2026. Version 2.1 and version 3.0 differ by more than 40 points on the same name today.
How to read the gaps honestly
Two published caveats should change how you rank this board.
The confidence intervals are wide. Every row carries a 95% confidence half-width between 2.45 and 3.94 points. Claude Opus 5.5 leads Claude Sonnet 5.5 by 3.03 points on intervals of 3.11 and 2.94, which is right at the edge of separable, so treat the top two as close rather than ranked. Opus 5.5’s 6.67-point lead over the next group is real. Below that, GPT-6.1 Sol and GPT-6 Astra at max tie exactly at 58.18%, and four more entries sit 0.30 points behind them at 57.88%, on intervals near 3. Those six are a tie, not a ranking. Lower down, Grok 4.5 and Claude Sonnet 5 both sit at 12.42%, and Grok 4.6 at 20.30% against GPT-5.6 Terra at 21.52% is 1.2 points on intervals of about 3.2, so that ordering is noise too.
Infrastructure alone moves scores by more than some gaps. The resource calibration in 4.0 follows Quantifying infrastructure noise in agentic coding evals, published by Gian Segato at Anthropic in February 2026. Running Terminal-Bench 2.0 across six resource configurations, from strictly enforced to entirely uncapped, produced a 6 percentage point gap between the most- and least-resourced setups. Its recommendation is explicit: leaderboard differences below 3 percentage points deserve skepticism until the evaluation configuration is documented and matched.
Applied here, the safe read is four tiers rather than 35 ranks. Claude Opus 5.5 and Claude Sonnet 5.5 lead, above 60%. GPT-6.1 Sol, GPT-6 Astra at high effort or above and Claude Fable 5.1 at xhigh and max form a tied group at 57.88% to 58.18%. Astra at medium and low, Claude Fable 5.1 at medium and high, and Claude Opus 5 at xhigh, max and high form a contested third group between 50% and 55%. Everything from GPT-6 Sol down is separated more by confidence interval and by harness than by demonstrated capability. The harness point is worth holding onto: the OpenAI models ran in Codex, the Claude, GLM and Qwen models in Claude Code, Grok in xAI’s own Grok Build, Muse Spark in Meta’s Muse Code and the Gemini models in mini-SWE-agent, so a cross-column comparison carries the agent as well as the model. Grok 4.7 is the clearest illustration on the board: the same weights score 37.58% here in Grok Build and 25.8% when Artificial Analysis runs them on a standardized harness.
What 4.1 and 5.0 will change
Neither has shipped. Both exist as open milestones on the Terminal-Bench repository, read on October 20, 2026:
- Terminal-Bench 4.1 is scoped to verifier improvements, specifically tamper-resistant verifiers, plus task fixes at minor and patch level. Because verifier-only changes are a minor version under the semantic policy, saved artifacts get re-graded rather than re-run, so scores can move without anyone paying for new rollouts. It now has 20 closed issues and 64 open, and a due date of September 26, 2026 that has passed.
- Terminal-Bench 5.0 is scoped to new tasks alongside significant task modifications to timeouts, resources and the agent environment. That is a breaking change by definition, so it will require full re-runs and will reset the board again. It has grown to 117 open issues, with 2 closed and no due date.
Treat any figure attributed to 5.0 before that milestone closes as unverified. The practical consequence for anyone citing these numbers is that the 64.85% ceiling is a snapshot with a known expiry, not a stable fact about Claude Opus 5.5. The 4.0 ceiling has already moved three times: 51.82% in August, 58.18% in September, 64.85% in October.
The practical read
If you are choosing a coding agent stack on this evidence, the board supports three conclusions and no more.
- Rank on cost per solved task, not on the score column. The accuracy ranking and the efficiency ranking disagree sharply. Claude Sonnet 5.5 is second on accuracy and costs $35.95 per solved task; Claude Opus 5.5 beats it on both. GPT-6 Astra at max and GPT-6.1 Sol post the identical 58.18%, and one costs five times the other. If you rank on the score column alone you can pay several times more than you need to for the same result.
- Do not assume the cheap model is the cheap option, or that the expensive one is expensive. Sonnet 5 is the first counter-example: joint cheapest Anthropic model per token, most expensive per unit of finished work by a factor of six. GPT-6 Astra is the second, running the other way: joint most expensive per token and, in September, the cheapest capable entry on the board. Both are explained by token burn on long-horizon tasks, which is a property of the work rather than of the price list. The cost-per-task tracker models the same effect across harnesses.
- Record the version, the effort and the harness with the number. A Terminal-Bench figure without a version is unusable, and 5.0 will invalidate the current board when it lands. That versioning discipline is why Terminal-Bench sits at the top of the benchmark trust ranking. Astra alone occupies five rows spanning 7.6 accuracy points and an 82% range in cost per solved task, so “GPT-6 Astra on Terminal-Bench 4.0” is not a specific enough citation to be worth anything.
Frequently asked questions
- What is Terminal-Bench 4.0?
- Terminal-Bench 4.0 is the August 28, 2026 release of the Terminal-Bench agentic command-line benchmark. It contains 66 containerized tasks, each attempted five times for 330 trials per leaderboard entry, with a flat 8-hour agent timeout. It removed 8 tasks and fixed 19 relative to version 3.0.
- Which model leads Terminal-Bench 4.0?
- As of October 20, 2026, Claude Opus 5.5 running in Claude Code at max effort leads with 64.85%, solving 214 of 330 trials. Claude Sonnet 5.5 is second at 61.82%, and GPT-6.1 Sol and GPT-6 Astra, both in Codex at max effort, tie third at 58.18%. The 95% confidence half-widths run from 2.45 to 3.94 points, so the gap between the top two is borderline, while Opus 5.5 is clearly ahead of the 58% group. The comparison carries the agent harness as well as the model.
- How much does it cost to solve one Terminal-Bench task?
- Dividing each entry published total cost by its solved trials gives a range from $1.34 for GPT-6 Luna to $234.24 for Claude Sonnet 5, a 175x spread. Among capable entries, GPT-6.1 Sol costs $3.30 per solved task, GPT-6 Astra $17.02 at max, Claude Opus 5.5 $22.05 and Claude Sonnet 5.5 $35.95. These are derived figures, not prices Terminal-Bench publishes, and a benchmark trial is a harder unit of work than a typical production task.
- Why is Claude Sonnet 5 the most expensive model on the board?
- Because of token volume, not per-token price. Terminal-Bench reports Sonnet 5 consuming 21.6 billion tokens on its run against 6.5 billion for Opus 5 and 1.53 billion for GPT-6 Astra, while hitting timeouts and output-token-exceeded errors. Its total bill of $9,603.86 is the largest on the board even though it scored 12.42%, second from the bottom.
- Can I compare a Terminal-Bench 2.1 score to a 4.0 score?
- No. Version 3.0 replaced the task set entirely with 74 new tasks, and 4.0 cut that to 66 and changed the resource limits. The current board tops are 87.4% on 2.1, 42.7% on 3.0 and 64.85% on 4.0. Those are three separate measurements that share a name. Movement within a single version is comparable: the 4.0 top score rose from 51.82% in August to 58.18% in September and 64.85% in October with no change to the task set, only new models entering.
- Did Claude Opus 5.5 and Sonnet 5.5 match their launch scores on Terminal-Bench 4.0?
- Opus 5.5 did, within the margin: Anthropic reported 66.4% and the independent board measures 64.85%, inside its 3.11-point interval. Sonnet 5.5 did not: Anthropic reported 70.6% and the board measures 61.82%, 8.8 points lower. Both runs used Claude Code at max effort. Sonnet 5.5 is still second on the board.
- Has Terminal-Bench 5.0 been released?
- Not as of October 20, 2026. Terminal-Bench 5.0 is an open GitHub milestone scoped to new tasks and significant environment changes, with 117 open issues, 2 closed and no due date. Version 4.1, scoped to tamper-resistant verifiers, is also unshipped, with 64 open issues and a September 26, 2026 due date that has passed.
Sources
- Marten, R. (2026). Terminal-Bench 4.0: Calibrating task resources, fixing tasks, and removing saturated tasks [announcement]. Terminal-Bench. Verified 2026-08-29. tbench.ai
- Terminal-Bench (2026). Terminal-Bench 4.0 leaderboard [accuracy, confidence intervals, solved counts, total cost and token counts for all 35 entries; board last updated 2026-10-06]. Verified 2026-10-20. tbench.ai
- Harbor Framework (2026). terminal-bench milestones v4.1 and v5.0 [open and closed issue counts, due dates]. GitHub. Verified 2026-10-20. github.com
- OpenAI (2026). API pricing [per-token rates used to reconcile the published GPT-6 Astra run cost]. OpenAI developer documentation. Verified 2026-09-04. developers.openai.com
- Terminal-Bench (2026). Terminal-Bench 3.0 [announcement; 74 tasks across 7 domains, per-version pass rates]. Verified 2026-08-29. tbench.ai
- Terminal-Bench (2026). Continuous Benchmarks [semantic versioning policy for patch, minor and major releases]. Verified 2026-08-29. tbench.ai
- Harbor Framework (2026). terminal-bench v4.0.0 [release notes naming the 8 removed tasks; task tree contains 66 directories]. GitHub. Verified 2026-08-29. github.com
- Segato, G. (2026). Quantifying infrastructure noise in agentic coding evals [engineering research; 6 percentage-point gap across six resource configurations on Terminal-Bench 2.0]. Anthropic, February 5, 2026. Verified 2026-08-29. anthropic.com
- Merrill, M. A., et al. (2026). Terminal-Bench: Benchmarking agents on hard, realistic tasks in command line interfaces [preprint]. arXiv:2601.11868. arxiv.org