Cost Per Token Over Time: The AI Price Collapse
How AI cost per token fell roughly 10x per year since 2021, why it collapsed, and why your per-task bill did not drop nearly as fast.
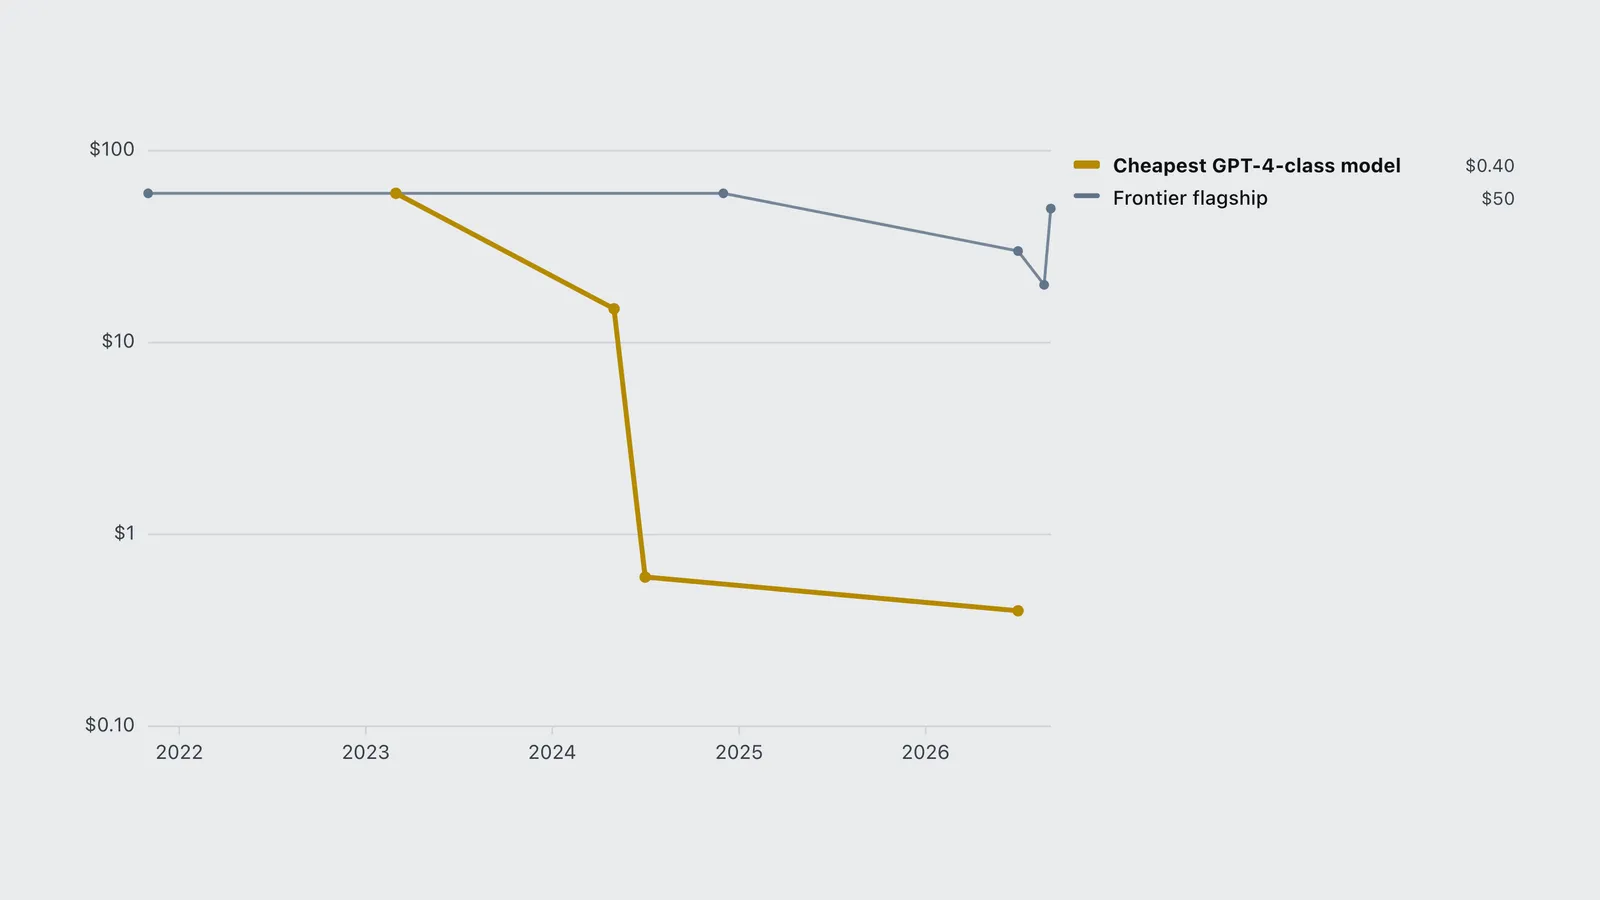
The cost per token of AI has fallen faster than almost any price in computing history. To buy the quality of the March 2023 GPT-4 today, you pay about $0.40 per million output tokens instead of $60, a 150-fold drop in a little over three years. The rate the whole industry quotes is cleaner still: for a model of equivalent performance, the price falls by roughly 10x every year.
That is the headline. The catch, and the reason this post exists, is that the number on your invoice has not fallen 10x a year. Per-token prices collapsed. Per-task bills did not. This is the gap between the two that matters, and it is where most cost planning goes wrong.
How far cost per token has fallen
Two prices tell the story, and they move in opposite ways. One is the price of the frontier flagship: the top price tier a lab sells as its best general model that year. The other is the price of a fixed capability: the cheapest model that matches or beats the original GPT-4. Plotting both on a logarithmic axis (each gridline is 10x the one below) shows the split clearly.
| Date | Cheapest GPT-4-class model | Top-tier flagship |
|---|---|---|
| 2021-11-01 | $60 | |
| 2023-03-14 | $60 | $60 |
| 2024-03-04 | $75 | |
| 2024-07-18 | $0.60 | |
| 2025-02-08 | $0.60 | |
| 2025-07-14 | $75 | |
| 2025-11-24 | $25 | |
| 2026-06-09 | $50 | |
| 2026-07-01 | $50 | |
| 2026-09-03 | $50 |
The gap between the two lines is the entire point. When GPT-4 launched, the best model and the cheapest way to get GPT-4 quality were the same thing, at $60 per million output tokens. Three years later the top tier sits at $50 per million (Claude Fable 5 since June 2026, matched by Claude Fable 5.1 and GPT-6 Astra in September), while GPT-4-level quality costs cents. The top tier was never on a downward path: it peaked at $150 with GPT-4.5 in 2025 and fell to $25 by that November before climbing back. The price of yesterday’s frontier is in free fall.
The single most-cited figure comes from a November 2024 Andreessen Horowitz analysis by Guido Appenzeller, Welcome to LLMflation: the cost to run a GPT-3-class model fell from $60 per million tokens in late 2021 to about $0.06 per million by 2024, a roughly 1,000-fold drop in three years. Appenzeller frames the trend as a 10x fall per year for a model of equivalent performance, with cost at fixed quality halving roughly every two months.
Independent measurement agrees on the direction and pushes the numbers further. Epoch AI, in its March 2025 data insight on LLM inference price trends, found prices falling between 9x and 900x per year depending on the task, with a median of 50x. Restricting the data to after January 2024, the median rose to 200x per year. The price to reach GPT-4’s level on a set of PhD-level science questions fell 40x per year.
| Item | Value |
|---|---|
| a16z: equivalent-quality model | 10x |
| Epoch: median across tasks | 50x |
| Epoch: median since Jan 2024 | 200x |
Why cost per token collapsed
The fall is not one thing. Four forces stack:
Hardware and serving efficiency. Newer accelerators, better batching, speculative decoding, quantization, and paged attention cut the compute cost of generating a token. This is the slow, compounding floor under everything else.
Distillation and smaller models. A small model trained on a large model’s outputs can reach a capability bar the large model set a year earlier, at a fraction of the parameters and therefore a fraction of the serving cost. GPT-4o mini, launched July 2024 at $0.15 in and $0.60 out per million tokens, was the moment sub-dollar output became normal for a genuinely useful model.
Competition. OpenAI’s own ladder shows the pressure: GPT-4 at $30/$60 in March 2023, GPT-4o at $5/$15 in May 2024, then a further cut months later. Every credible rival that ships forces the incumbents to reprice.
Open weights and Chinese labs. The cheapest capable models on the market are now often open-weight or Chinese-hosted. DeepSeek, Kimi, GLM, and Qwen list frontier-adjacent quality at output prices a fraction of the US flagships. The mechanics of that gap are their own story, covered in why Chinese AI models are so cheap.
Why your bill did not fall 10x a year
Here is the trap. If per-token prices fall 10x a year, it is tempting to assume last year’s workload now costs a tenth as much. It almost never does. Three reasons.
Reasoning models emit far more tokens per task. The 2026 models that top the leaderboards think before they answer, producing long chains of internal reasoning tokens that you pay for. A task that cost 2,000 output tokens on GPT-4 in 2023 can cost 20,000 on a reasoning model today. A 10x drop in price per token is cancelled by a 10x rise in tokens per task. This is the core of the price reversal phenomenon, where the cheaper-per-token model finishes the job at higher total cost.
Context has grown. Bigger context windows invite bigger prompts: whole codebases, long documents, full chat histories re-sent every turn. Input tokens per request have climbed as fast as models allowed them to. Many surprise invoices are input-side, not output-side, as traced in why your AI API bill is so high.
People buy up, not sideways. When quality gets cheaper, most teams do not bank the saving. They move to the newest, most capable (and most expensive) model, because it unlocks work the old one could not do. The frontier price never fell, so buying the frontier never got cheaper.
Cost per token over time: the anchor points
The top-tier flagship is the most expensive top-tier general model on sale from OpenAI, Anthropic or Google at each date. The GPT-4-class floor is the cheapest model at or above the original March 2023 GPT-4 quality bar. All prices are standard list output rates per million tokens, including launch promotions while they ran, and each holds until the next row changes it.
| Date | Top-tier flagship | GPT-4-class floor |
|---|---|---|
| Nov 2021 | GPT-3 davinci, $60 | (GPT-4 not yet released) |
| Sep 2022 | GPT-3 davinci, $20 (price cut) | |
| March 2023 | GPT-4, $60 | GPT-4, $60 |
| Nov 2023 | GPT-4 Turbo, $30 | GPT-4 Turbo, $30 |
| March 2024 | Claude 3 Opus, $75 | |
| May 2024 | GPT-4o, $15 | |
| July 2024 | GPT-4o mini, $0.60 | |
| Dec 2024 | DeepSeek-V3, $0.28 (launch promotion) | |
| Feb 2025 | GPT-4.5, $150 | GPT-4o mini, $0.60 (promotion ended) |
| July 2025 | Claude Opus 4, $75 (GPT-4.5 left the API) | Gemini 2.5 Flash-Lite, $0.40 |
| Nov 2025 | Claude Opus 4.5, $25 | |
| April 2026 | GPT-5.5, $30 | DeepSeek V4 Flash, $0.28 |
| June 2026 | Claude Fable 5, $50 (suspended June 12) | |
| July 2026 | Claude Fable 5, $50 (restored July 1) | |
| Aug 2026 | Gemini 2.5 Flash-Lite, $0.40 | |
| Sep 2026 | GPT-6 Astra and Claude Fable 5.1, $50 |
Update, 2026-10-27: this table and the chart were rebuilt as step series from launch posts and archived pricing pages. The earlier version skipped from OpenAI o1 (December 2024) to GPT-5.6 Sol (July 2026), which hid the $150 GPT-4.5 peak and the fall to $25, and dated the return to $50 to September 2026 when Claude Fable 5 had charged it since June. Two rules govern it. The flagship is each lab’s newest top-tier general model at standard context, excluding Pro variants such as o1-pro and GPT-5.5 Pro. The floor counts a model when it matches or beats GPT-4o mini (82% on MMLU) on its lab’s own results, which rules out Gemini 1.5 Flash and Gemini 2.0 Flash-Lite despite their $0.30 output rates. The top tier and the top score have also split: on September 22, 2026 Anthropic released Claude Opus 5.5 at $4 input and $20 output per million tokens, and the independent Artificial Analysis index scores it 58 against 53 for both $50 models (read 2026-10-27).
For current per-token rates across every tracked model, see the AI model release tracker and pricing. For what these rates mean once you turn them into a monthly subscription, see the AI coding plan pricing pillar. And for the case where cheap tokens still lose to owned hardware, see self-hosted LLM cost per token.
What it means for planning
The practical rule: index your budget to capability, not to price per token. If you pin yourself to a fixed quality level, your costs will fall dramatically year over year, and you can plan on it. If you always chase the top tier, expect no trend at all: it has swung between $20 and $150 per million output tokens since 2021, and sits at $50 today. The top score no longer needs the top tier, though: Claude Opus 5.5 leads the independent index at $20.
The deflation is real, and it is the strongest tailwind in the industry. It just does not arrive as a smaller invoice unless you choose to let it.
Frequently asked questions
- How much has the cost per token of AI fallen over time?
- For a fixed capability level, the cost per token has fallen roughly 10x per year since 2021, according to Andreessen Horowitz. Buying original GPT-4 quality dropped from about $60 to about $0.40 per million output tokens between March 2023 and 2026 at standard list rates, roughly 150x. Epoch AI measures a median 50x-per-year fall across tasks, rising to 200x per year for data since January 2024.
- Why is my AI bill not falling if prices drop 10x a year?
- Because per-token price and per-task cost are different. Reasoning models emit many more tokens per task than older models, and context windows have grown, so tokens-per-request has risen even as price-per-token fell. Most teams also upgrade to the newest, most expensive model rather than bank the saving. The result is a bill that falls far slower than the token price.
- Why does the frontier flagship price not fall like everything else?
- Because the top tier is not a fixed product. Each time a lab ships a bigger model it sets a new premium: Claude 3 Opus at $75 per million output tokens in 2024, GPT-4.5 at $150 in 2025. Then a cheaper successor resets it, as Claude Opus 4.5 did at $25 that November. Since June 2026 the top tier has been back at $50, with Claude Fable 5, Claude Fable 5.1 and GPT-6 Astra. What collapses in price continuously is yesterday’s frontier, once cheaper models match it.
- What is LLMflation?
- LLMflation is the term Andreessen Horowitz coined in November 2024 for the rapid fall in LLM inference cost: for a model of equivalent performance, cost drops about 10x per year, halving roughly every two months. It describes the deflation in the price of a fixed AI capability, not the price of the frontier.
Sources
- Appenzeller, Guido (2024). Welcome to LLMflation: LLM inference cost is going down fast. Andreessen Horowitz. a16z.com
- Epoch AI (2025). LLM inference prices have fallen rapidly but unequally across tasks. Data insight. epoch.ai
- OpenAI (2024). Hello GPT-4o (GPT-4o pricing $5/$15 per million tokens). openai.com
- OpenAI (2024). GPT-4o mini: advancing cost-efficient intelligence ($0.15/$0.60 per million tokens). openai.com
- OpenAI (2023). GPT-4 API general availability ($30/$60 per million tokens at launch). openai.com
- OpenAI (2022). The OpenAI API is now more affordable (GPT-3 davinci $0.06 to $0.02 per 1K tokens from September 1, 2022). Community announcement. community.openai.com
- TechCrunch (2023). OpenAI launches GPT-4 Turbo ($10/$30 per million tokens, November 6, 2023). Secondary report. techcrunch.com
- Anthropic (2024). Introducing the next generation of Claude (Claude 3 Opus $15/$75). anthropic.com
- DeepSeek (2024). DeepSeek-V3 release note (“Until Feb 8: same as V2!”, then $0.27/$1.10). Internet Archive capture. web.archive.org
- TechCrunch (2025). OpenAI plans to wind down GPT-4.5 in its API ($75/$150; removed July 14, 2025). Secondary report. techcrunch.com
- Anthropic (2025). Introducing Claude 4 (Claude Opus 4 $15/$75). anthropic.com
- Google (2025). Gemini 2.5 Flash-Lite is now stable and generally available ($0.10/$0.40, July 22, 2025). developers.googleblog.com
- Reuters via Investing.com (2025). Anthropic launches Claude Opus 4.5 ($5/$25, November 24, 2025). Secondary report. investing.com
- Let’s Data Science (2026). OpenAI GPT-5.5, six weeks after 5.4, doubled price ($5/$30, API from April 24, 2026). Secondary report. letsdatascience.com
- DeepSeek (2026). Models and pricing (deepseek-v4-flash $0.14/$0.28). Internet Archive capture, April 26, 2026. web.archive.org
- Google (2026). Gemini API pricing (Gemini 2.5 Flash-Lite Standard tier $0.10/$0.40 per million tokens; $0.05/$0.20 is the Batch and Flex rate). ai.google.dev