GPT-6.2 Astra and Sol: Pricing, Benchmarks, Cost per Task
GPT-6.2 Astra costs $8/$40 per million tokens, 20% under GPT-6 Astra. At xhigh effort it matches Claude Fable 5.2's default score for 28% of the cost.
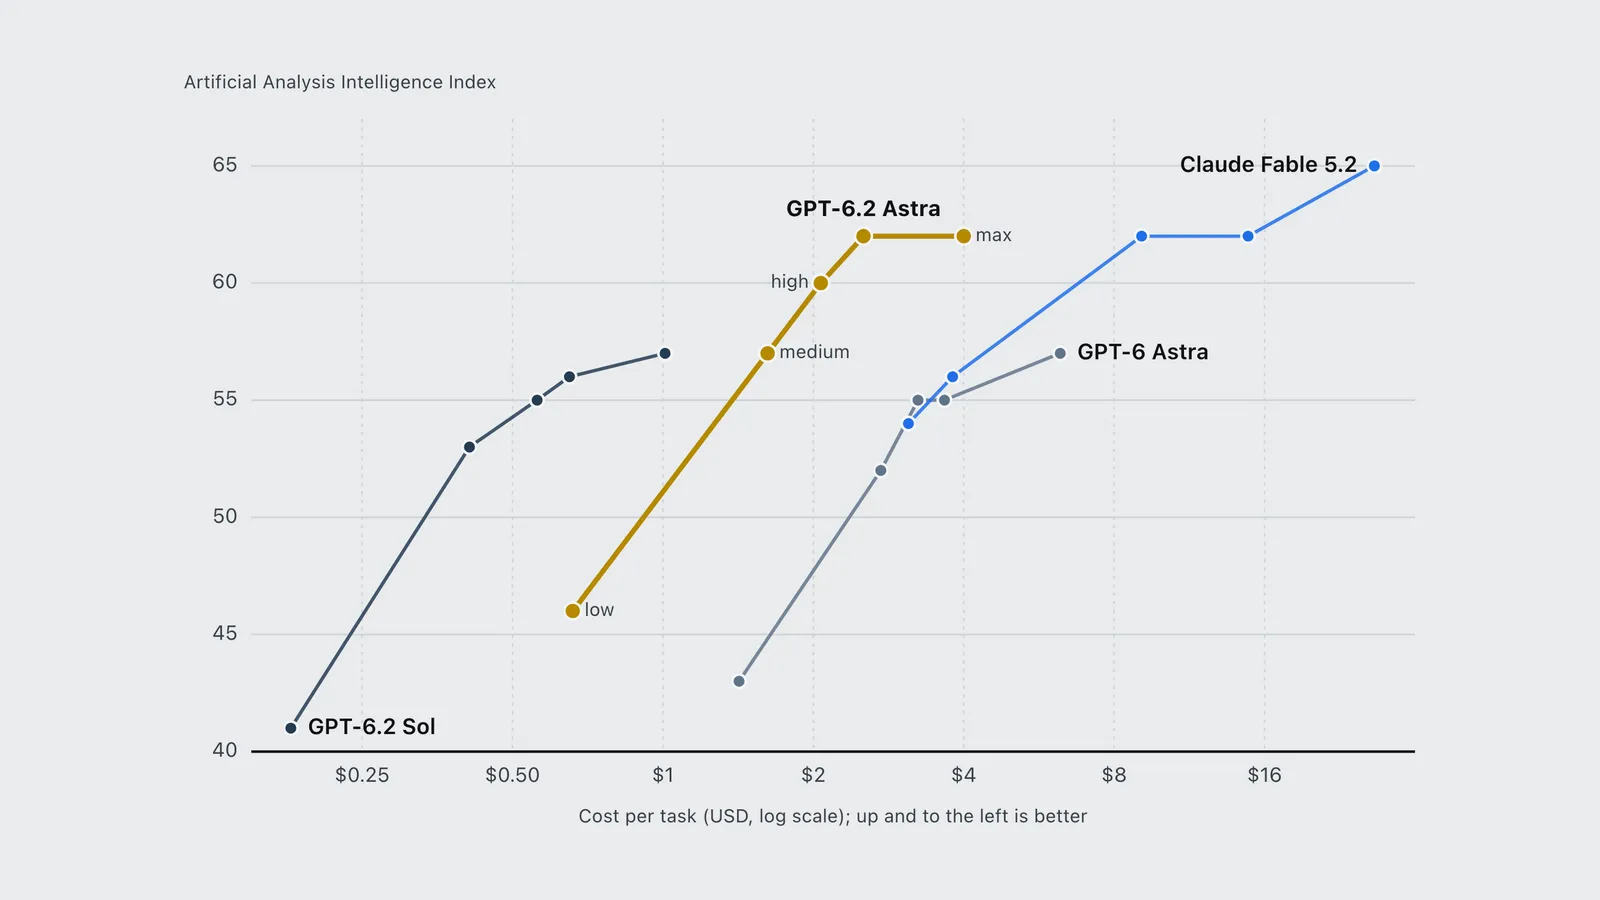
GPT-6.2 Astra costs $8 per million input tokens and $40 per million output, 20% less than GPT-6 Astra, and any OpenAI API key can call it today. At xhigh effort it scores 62 on the independent Artificial Analysis index for $2.52 a task, the score Claude Fable 5.2 needs $9.08 to reach.
OpenAI released GPT-6.2 Astra and GPT-6.2 Sol on November 17, 2026, eight days after Claude Fable 5.2 launched at the same $8 and $40. Sol keeps the $2 and $10 that GPT-6.1 Sol charged and scores two points higher on the index for 20% less per task. The verdict: for any score up to 62, OpenAI is now the cheaper buy. Fable 5.2 keeps only the top three points, at $26.54 a task.
| GPT-6.2 Astra and Sol | Rate or status |
|---|---|
| Astra input / output | $8 / $40 per Mtok (GPT-6 Astra: $10 / $50) |
| Astra cached input | $0.40 per Mtok (GPT-6 Astra: $1.00) |
| Sol input / output | $2 / $10 per Mtok, cached $0.10 (unchanged from GPT-6.1 Sol) |
| Who can use them | API; ChatGPT Work and Codex on Plus, Pro, Enterprise and Edu |
| Not available in | Regular ChatGPT chat |
| Context, max output | 1,050,000 tokens, 128,000 tokens |
| Cost per AA index task | Astra $2.52 at xhigh, $4.00 at max; Sol $1.01 at max |
| Introductory rate | None; Ultrafast is 3x standard through February 28, 2027, then 6x |
How much does GPT-6.2 Astra cost?
$8 per million input tokens and $40 per million output, read from OpenAI’s GPT-6.2 Astra model documentation. Input and output fell 20% against GPT-6 Astra. The cache read fell 60%, from $1.00 to $0.40, which matters more than the headline for an agent that re-reads its own context on every turn.
| Rate, per Mtok | GPT-6.2 Astra | GPT-6 Astra | Claude Fable 5.2 | GPT-6.2 Sol |
|---|---|---|---|---|
| Input | $8.00 | $10.00 | $8.00 | $2.00 |
| Cached input | $0.40 | $1.00 | $0.20 | $0.10 |
| Output | $40.00 | $50.00 | $40.00 | $10.00 |
| Short cache write | $10.00 | $12.50 | $10.00 | $2.50 |
| Long cache write | $20.00 | not listed | $16.00 | $5.00 |
| Prompts over 272K tokens | $16 / $60 | $20 / $75 | not listed | $4 / $15 |
| Batch input / output | $4 / $20 | $5 / $25 | $4 / $20 | $1 / $5 |
| Fast mode input / output | $16 / $80 | $20 / $100 | $16 / $80 | $4 / $20 |
OpenAI’s short cache write keeps a prompt for 30 minutes and its long one for 12 hours; Anthropic’s are 5 minutes and 1 hour. On the rate card, Fable 5.2 is the cheaper of the two only on cached input, at half Astra’s $0.40. Astra also adds a surcharge above 272,000 tokens: the whole request bills at double input and 1.5 times output. Fable 5.2’s surcharge terms are not covered here; check Anthropic’s pricing page for long prompts.
Ultrafast, OpenAI’s fastest tier, runs at three times the standard rate through February 28, 2027 and six times from March 1, per the same documentation. That is $24 and $120 for Astra until the end of February. GPT-6 Astra’s Ultrafast launched at $60 and $300.
What does a task cost on GPT-6.2 Astra?
Less than on GPT-6 Astra at every effort setting, and more score at every one. Artificial Analysis, an independent benchmarking service, ran its Intelligence Index on GPT-6.2 Astra at all five effort levels and published a cost per task for each. Read on November 18, 2026:
| Effort | GPT-6.2 Astra score | Cost per task | GPT-6 Astra score | Cost per task |
|---|---|---|---|---|
| low | 46 | $0.66 | 43 | $1.42 |
| medium | 57 | $1.62 | 52 | $2.73 |
| high | 60 | $2.07 | 55 | $3.24 |
| xhigh | 62 | $2.52 | 55 | $3.66 |
| max | 62 | $4.00 | 57 | $6.24 |
The step to watch is xhigh to max. Both display as 62 on the index (61.6 against 62.1), so max adds $1.48 a task, 59% more, for a fraction of a point. On this index, xhigh is where Astra stops getting better for the money.
OpenAI’s launch claim is that GPT-6.2 Astra gets its results “at less than a third of the cost per task of GPT‑6 Astra,” per its developer-forum announcement. On Artificial Analysis that holds when you match the score, not the setting: GPT-6.2 Astra at medium scores 57 for $1.62, against $6.24 for GPT-6 Astra at max, 26% of the cost. Compared at max against max, the new model costs 64% of the old one.
Where the saving comes from is not where the headline suggests. At max effort GPT-6.2 Astra writes 65.8 million output tokens to finish the index, 21% more than GPT-6 Astra’s 54.3 million, so its output spend barely moves: about $2,630 for the run against $2,716. The drop is on the input side. Its cache-read spend falls 48%, from about $1,567 to $817, because the cache read now costs $0.40 instead of $1.00. All of these are Artificial Analysis figures for one full index run.
| Model | Effort | Artificial Analysis Intelligence Index | Cost per task |
|---|---|---|---|
| GPT-6.2 Astra | low | 46 | $0.66 |
| GPT-6.2 Astra | medium | 57 | $1.62 |
| GPT-6.2 Astra | high | 60 | $2.07 |
| GPT-6.2 Astra | xhigh | 62 | $2.52 |
| GPT-6.2 Astra | max | 62 | $4.00 |
| GPT-6 Astra | low | 43 | $1.42 |
| GPT-6 Astra | medium | 52 | $2.73 |
| GPT-6 Astra | high | 55 | $3.24 |
| GPT-6 Astra | xhigh | 55 | $3.66 |
| GPT-6 Astra | max | 57 | $6.24 |
| GPT-6.2 Sol | low | 41 | $0.18 |
| GPT-6.2 Sol | medium | 53 | $0.41 |
| GPT-6.2 Sol | high | 55 | $0.56 |
| GPT-6.2 Sol | xhigh | 56 | $0.65 |
| GPT-6.2 Sol | max | 57 | $1.01 |
| Claude Fable 5.2 | low | 54 | $3.10 |
| Claude Fable 5.2 | medium | 56 | $3.80 |
| Claude Fable 5.2 | high | 62 | $9.08 |
| Claude Fable 5.2 | xhigh | 62 | $15 |
| Claude Fable 5.2 | max | 65 | $27 |
Is GPT-6.2 Astra better than Claude Fable 5.2?
Cheaper for the same score, but not higher at the top. The two share a rate card, and the independent results split by what you measure:
| Independent result | GPT-6.2 Astra | Claude Fable 5.2 | Who leads |
|---|---|---|---|
| AA Intelligence Index, best setting | 62 (max), $4.00 | 65 (max), $26.54 | Fable 5.2 |
| AA index, cheapest route to 62 | xhigh, $2.52 | high, $9.08 | Astra, 72% cheaper |
| Terminal-Bench 4.0 on Vals, accuracy | 63.13% | 65.15% | Fable 5.2 |
| Terminal-Bench 4.0 on Vals, cost per test | $4.69 | $14.56 | Astra, 68% cheaper |
| ARC-AGI-3, standard harness | 70.3% (max) | 81.2% | Fable 5.2 |
| ARC-AGI-2 | 95.8% (max, xhigh) | below 95.8% | Astra |
The Artificial Analysis gap comes from tokens. GPT-6.2 Astra at xhigh writes 27.1 million output tokens to finish the index. Fable 5.2 at high writes about 85 million for the same 62, at the same $40 per million. On the same rate card, the model that does the work in a third of the tokens costs about a third as much.
Vals AI, an independent evaluator, runs Terminal-Bench 4.0 with the same minimal agent harness for every model, averaged over three runs. Fable 5.2 and Claude Opus 5.5 tie for first at 65.15%; GPT-6.2 Astra ties Gemini 4 Carbon at 63.13% for $4.69 a test, against $14.56 for Fable 5.2 and $7.45 for Carbon. GPT-6.2 Sol scores 60.61% for $1.13. The official tbench.ai board has moved to Terminal-Bench 4.1 and had not listed either GPT-6.2 model when checked on November 18.
ARC Prize verified both models on launch day. GPT-6.2 Astra now holds the top ARC-AGI-2 score at 95.8%, and ties several models at 98.5% on the finished ARC-AGI-1. On ARC-AGI-3, the interactive test, it scores 70.3% at max on the standard harness, behind Fable 5.2’s 81.2% on the ARC Prize leaderboard. On OpenAI’s own Provider Adapter harness, which keeps reasoning state between turns, Astra scores 100.0% at xhigh. That is the same harness caveat as at GPT-6 Astra’s launch, and the standard number is the one to compare. What each of these tests measures is in the AI benchmarks directory.
Is GPT-6.2 Astra better than GPT-6 Astra?
On everything published so far. Besides the Artificial Analysis table above, OpenAI’s GPT-6.2 system card reports these scores. They are vendor-reported, and only the system card’s comparisons with GPT-6 Astra are shown:
| Benchmark (vendor-reported) | GPT-6.2 Astra | GPT-6.2 Sol | GPT-6 Astra |
|---|---|---|---|
| ExploitBench Internal Port (code execution) | 53.5% | 50.5% | 31.5% |
| SEC-Bench Pro (pass@1) | 86.75% | 88.34% | 85.4% |
| GPQA Diamond, no tools | 97.0% | 96.0% | 96.0% |
| MLE-Bench Revised (mean percentile) | 96.06 | 91.38 | 93.80 |
| KernelGen 1P | 76.92% | 74.71% | 66.72% |
| Internal Research Debugging | 81.85% | 74.66% | 78.05% |
The ExploitBench jump is the one OpenAI leads with: 22 points over GPT-6 Astra, which makes this its most capable cyber model so far. The same system card says both models meet OpenAI’s Critical threshold for cybersecurity capability, so higher-risk security requests face tighter safeguards. OpenAI says it is working to bring the models to Daybreak, its programme for approved defenders, with fewer refusals. MLE-Bench and Internal Research Debugging are two rows where GPT-6.2 Sol scores below the old Astra.
OpenAI’s forum announcement adds two claims without absolute scores. On Agents’ Last Exam, GPT-6.2 Astra at xhigh scores 5.2 points above GPT-6 Astra at max “at less than half the cost per task.” On FrontierCode 2.0, GPT-6.2 Sol “nearly matches Astra” on merge-ready changes to real codebases at about one fifth of the cost. Neither has been reproduced.
How much does GPT-6.2 Sol cost, and is it better than GPT-6.1 Sol?
$2 per million input tokens, $0.10 cached and $10 output, the same as GPT-6.1 Sol, per the GPT-6.2 Sol model documentation. It is better at every effort setting, and cheaper per task at three of the five:
| Effort | GPT-6.2 Sol score | Cost per task | GPT-6.1 Sol score | Cost per task |
|---|---|---|---|---|
| low | 41 | $0.18 | 35 | $0.16 |
| medium | 53 | $0.41 | 46 | $0.36 |
| high | 55 | $0.56 | 50 | $0.59 |
| xhigh | 56 | $0.65 | 52 | $0.76 |
| max | 57 | $1.01 | 55 | $1.27 |
At max, GPT-6.2 Sol ties GPT-6.2 Astra at medium on the index (57) for 62% of the cost. On Artificial Analysis readings of November 18 it is the cheapest publicly callable way to any score from 50 to 57: medium reaches 53 for $0.41, which nothing else on the index matches for less. Its knowledge cutoff is June 1, 2026, two weeks later than Astra’s May 18.
Pro 200 subscribers get Ultrafast for the first time with GPT-6.2 Sol, per the forum announcement; Pro 500 subscribers get it on both models.
Who can use GPT-6.2 Astra and Sol?
Anyone with an OpenAI API key, as gpt-6.2-astra and gpt-6.2-sol, on the Chat Completions, Responses and Batch endpoints. In ChatGPT, both are in ChatGPT Work and Codex for Plus, Pro, Enterprise and Edu users from November 17, rolling out by plan and workspace setting. OpenAI staff said in the forum thread that the release does not add either model to regular Chat.
Both models take text and image input and return text, with a 1,050,000-token context and up to 128,000 output tokens. Neither supports Realtime, fine-tuning or audio. The API rejects a reasoning effort of none on both, so the cheapest setting is low.
Should you switch to GPT-6.2 Astra?
If you run GPT-6 Astra, yes: switching the model ID to gpt-6.2-astra buys 20% lower rates and a higher score at every effort setting. A workload pinned to gpt-6-astra still bills $10 and $50.
If you are choosing between labs, it depends on the score you need:
- Need the highest independent score? Claude Fable 5.2 at max, 65 on the index, at $26.54 a task. Nothing else reaches it.
- Fine at 60 to 62? GPT-6.2 Astra at high or xhigh, $2.07 to $2.52 a task, under a third of the Fable 5.2 route to the same score.
- Fine at about 57? GPT-6.2 Sol at max, $1.01. Astra at medium reaches the same 57 for $1.62.
- Running long agentic coding work? Check the Terminal-Bench numbers before the index: Fable 5.2 and Opus 5.5 lead Vals’ run by two points, and Astra costs about a third as much per test.
Index scores drift between readings; the figures here are from November 18, 2026. Rates for every model are on the AI model tracker, and the AI coding cost calculator prices a workload at a chosen rate card. Every November release is in new AI models released in November 2026, and the model this one replaces is in GPT-6 Astra: pricing, benchmarks, cost.
Frequently asked questions
- How much does GPT-6.2 Astra cost?
- GPT-6.2 Astra costs $8 per million input tokens and $40 per million output tokens, 20% less than GPT-6 Astra. Cached input costs $0.40, down from $1.00. Prompts over 272,000 tokens bill at $16 and $60, batch is half price, and there is no introductory rate.
- How much does GPT-6.2 Sol cost?
- GPT-6.2 Sol costs $2 per million input tokens, $0.10 cached and $10 output, unchanged from GPT-6.1 Sol. On the Artificial Analysis index it scores 57 at max effort for $1.01 a task, against 55 and $1.27 for GPT-6.1 Sol.
- Is GPT-6.2 Astra better than Claude Fable 5.2?
- It is cheaper for the same score but not higher at the top. On Artificial Analysis, GPT-6.2 Astra reaches 62 at xhigh for $2.52 a task, against $9.08 for Fable 5.2 at high, but only Fable 5.2 reaches 65. Fable 5.2 also leads on Terminal-Bench 4.0 and ARC-AGI-3.
- Is GPT-6.2 Astra in ChatGPT?
- Yes, in ChatGPT Work and Codex for Plus, Pro, Enterprise and Edu users from November 17, 2026. OpenAI said the release does not add GPT-6.2 Astra or Sol to regular ChatGPT chat.
- What effort level should I use with GPT-6.2 Astra?
- Start at high or xhigh. On Artificial Analysis, high scores 60 for $2.07 a task and xhigh 62 for $2.52. Max also displays 62 but costs $4.00, so it adds 59% to the bill for a fraction of a point.
- Is GPT-6.2 Astra cheaper than GPT-6 Astra per task?
- Yes, at every effort setting. At max it costs $4.00 per Artificial Analysis index task against $6.24, and it reaches GPT-6 Astra’s best score of 57 at medium effort for $1.62, about a quarter of the cost.
Sources
OpenAI (2026). GPT-6.2 Astra and GPT-6.2 Sol. OpenAI developer model documentation: rates, cache writes, long-context and batch pricing, Ultrafast multipliers, context, knowledge cutoff, endpoints. https://developers.openai.com/api/docs/models/gpt-6.2-astra and https://developers.openai.com/api/docs/models/gpt-6.2-sol Read 2026-11-18.
OpenAI (2026). GPT-6.2 Astra and Sol are now available. OpenAI Developer Community announcement, November 17, 2026: availability, Ultrafast access, launch cost-per-task and benchmark claims. https://community.openai.com/t/gpt-6-2-astra-and-sol-are-now-available/1417531 Read 2026-11-18.
OpenAI (2026). GPT-6.2 System Card. OpenAI Deployment Safety Hub, November 17, 2026: vendor-reported capability evaluations and Preparedness classifications. https://deploymentsafety.openai.com/gpt-6-2-astra-sol Read 2026-11-18.
Artificial Analysis (2026). GPT-6.2 Astra, GPT-6.2 Sol, GPT-6 Astra, GPT-6.1 Sol and Claude Fable 5.2 model pages and the Models leaderboard. Independent benchmarking service: Intelligence Index scores, cost per task and token counts by effort setting. https://artificialanalysis.ai/models/gpt-6-2-astra, https://artificialanalysis.ai/models/gpt-6-2-sol and https://artificialanalysis.ai/leaderboards/models Read 2026-11-18.
Vals AI (2026). Terminal-Bench 4.0. Independent leaderboard, mini-SWE-agent harness, average of three runs. https://www.vals.ai/benchmarks/terminal-bench-4 Read 2026-11-18.
ARC Prize (2026). OpenAI GPT-6.2 results and ARC-AGI leaderboard. Verified ARC-AGI-1, -2 and -3 scores by effort setting. https://arcprize.org/results/openai-gpt-6-2 and https://arcprize.org/leaderboard Read 2026-11-18.
Anthropic (2026). Pricing. Claude Platform documentation: Claude Fable 5.2 rates. https://platform.claude.com/docs/en/about-claude/pricing Read 2026-11-10.