New AI Models Released in November 2026: Prices
Every AI model released in November 2026, with dates, verified launch prices and a primary source for each. Updated through the month as releases land.
Twenty-two AI models were released in November 2026 through the 17th, from thirteen labs. The newest two are OpenAI’s GPT-6.2 Astra and GPT-6.2 Sol on November 17: Astra at $8 and $40 per million tokens, 20% under GPT-6 Astra and the same headline rate as Claude Fable 5.2, and Sol at GPT-6.1 Sol’s unchanged $2 and $10. The day before, Alibaba released Qwen4-Max at $1.50 and $4.50, 25% under Qwen3.8-Max, and Tencent released Hy4 flash at $0.07 and $0.281, the cheapest per-token chat model of the month. The month’s top score belongs to Anthropic’s Claude Fable 5.2 on November 9, at $8 and $40 per million tokens and 62 on the independent Artificial Analysis index at its default effort. Google’s Gemini 4 Hydrogen followed on November 12 at $1.50 and $7.50, scoring 51, one point above the Gemini 4 Argon that costs more.
The quick verdict for anyone choosing today: GPT-6.2 Astra if you need a score in the low 60s, since it reaches 62 on the independent Artificial Analysis index at xhigh effort for $2.52 a task against $9.08 for Fable 5.2 at high. Claude Fable 5.2 only if you need the top three points (65 at max, $26.54 a task). GPT-6.2 Sol is the cheapest way to any score from 50 to 57, at $1.01 a task or less. Gemini 4 Hydrogen is the new mid-price default to test, since it outscores Argon for less on both lines. Qwen4-Max is the cheapest model above 40 on output price among this month’s releases, if a Chinese proprietary model is allowed. For cheap, high-volume text work, Meta’s Muse Ember matches Claude Haiku 5.5’s $0.10 and $0.50 rate card and scores 36 for $0.14 a task. Hy4 flash is cheaper per token than any of them, but no independent lab has scored it yet.
Every AI model released in November 2026
| Model | Provider | Released | Launch price | What it is |
|---|---|---|---|---|
| Hy4 | Tencent | Nov 4 | $0.834 / $2.501 per Mtok | Tencent’s flagship with vision and computer use, 35 on the AA index |
| SWE-2 Flash | Cognition | Nov 4 | Free in Devin to Dec 4, then $0.10 / $0.50 | Devin coding model on Inkling-Small, weights held back |
| Ripple-65B Preview | Ricursive Intelligence | Nov 4 | Self-hosted, no rate | Dense 65B open-weight coding preview, Apache 2.0 |
| GPT Image 2.6 Flare | OpenAI | Nov 4 | $8 image in / $30 image out per Mtok | Adds SVG and animated GIF output at the GPT Image 2.5 rate card |
| GPT Image 2.6 Sunburst | OpenAI | Nov 4 | $8 image in / $30 image out per Mtok | The precision-control 2.6 variant, same rates as Flare |
| GPT-6 Cyber | OpenAI | Nov 5 | $20 / $100 per Mtok (up to 272K) | Vulnerability research model, trusted-access security teams only |
| Gemini Omni 1.2 Flash | Nov 5 | $0.07 per second of 720p video | Video generation, 30% below Omni 1.1 Flash, clips up to 15 seconds | |
| Inkling 2 Small | Thinking Machines | Nov 5 | $0.30 / $1.00 per Mtok | 594B open-weight MoE (17B active), Apache 2.0, 31 on the AA index |
| Celeris-1.1 Decision | Celeris | Nov 5 | $0.004 input / $0 output per Mtok | Decision model, a tenth of Celeris-1’s input rate |
| Claude Fable 5.2 | Anthropic | Nov 9 | $8 / $40 per Mtok | 20% under Fable 5.1, 62 on the AA index at default high, 65 at max |
| Claude Mythos 5.2 | Anthropic | Nov 9 | $8 / $40 per Mtok | Fable 5.2 without its cyber and biology safeguards, verified organizations |
| Muse Ember | Meta | Nov 9 | $0.10 / $0.50 per Mtok | Meta’s smallest Muse, 36 on the AA index for $0.14 a task |
| Scribe v3 | ElevenLabs | Nov 10 | $0.20 per audio hour | Speech-to-text in 102 languages, 27% fewer word errors than v2 |
| Scribe v3 Live | ElevenLabs | Nov 10 | $0.22 per audio hour | Streaming tier of Scribe v3 |
| Gemini Decision 1 | Nov 11 | $0.10 input / $0 output per Mtok | Google’s first decision model, up to 1,000 questions per request | |
| MiniMax H3-Image | MiniMax | Nov 11 | No USD price published | Open-weight image model under a community licence |
| ERNIE 5.5 Flash Preview | Baidu | Nov 11 | Yuan pricing only | 280B MoE checkpoint (14B active), 1M context, weights promised |
| Gemini 4 Hydrogen | Nov 12 | $1.50 / $7.50 per Mtok | Gemini 4 successor to 3.8 Flash, 51 on the AA index at default high | |
| Qwen4-Max | Alibaba | Nov 16 | $1.50 / $4.50 per Mtok | Next-generation Qwen flagship, 25% under Qwen3.8-Max, 43 on the AA index |
| Hy4 flash | Tencent | Nov 16 | $0.07 / $0.281 per Mtok | 224B MoE (12B active) distilled from Hy4, not yet independently scored |
| GPT-6.2 Astra | OpenAI | Nov 17 | $8 / $40 per Mtok | Replaces GPT-6 Astra 20% cheaper, 62 on the AA index at max and xhigh |
| GPT-6.2 Sol | OpenAI | Nov 17 | $2 / $10 per Mtok | Replaces GPT-6.1 Sol at the same rates, 57 on the AA index at max |
Which November model gives the most score per dollar?
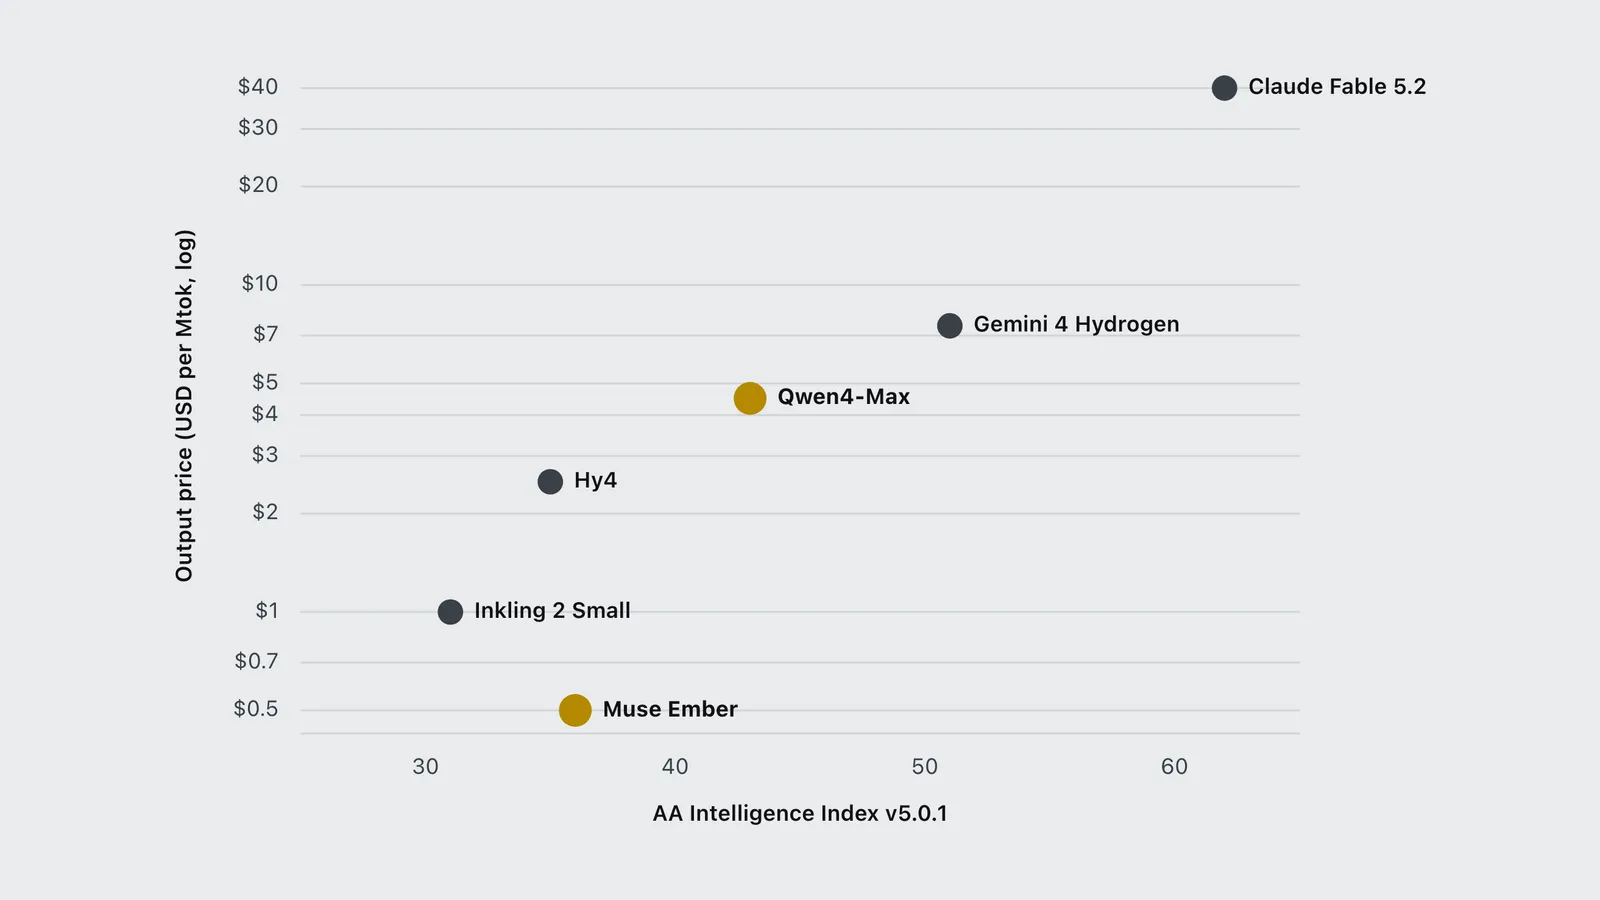
Read the November releases that have an independent score against what they charge for output, and two things stand out. The index climbs much more slowly than the price: Claude Fable 5.2 scores 11 points above Gemini 4 Hydrogen for 5.3 times the output rate, and GPT-6.2 Astra, at the same $40 as Fable, scores 3 points under it. And the cheap end is crowded with models in the 30s, where Muse Ember at $0.50 outscores both Hy4 at $2.50 and Inkling 2 Small at $1.00.
| Item | AA Intelligence Index v5.0.1 | Output price (USD per Mtok, log) |
|---|---|---|
| Claude Fable 5.2 | 65 | $40 |
| GPT-6.2 Astra | 62 | $40 |
| GPT-6.2 Sol | 57 | $10 |
| Gemini 4 Hydrogen | 54 | $7.5 |
| Qwen4-Max | 43 | $4.5 |
| Muse Ember | 36 | $0.5 |
| Hy4 | 35 | $2.501 |
| Inkling 2 Small | 31 | $1 |
Output price is only half of a bill, and a model that writes more tokens per task can cost more than its rate suggests. Where Artificial Analysis publishes a cost per index task, it mostly tells the same story: Muse Ember costs $0.14 a task, Hy4 $1.03, Qwen4-Max $3.27 and Fable 5.2 $9.08 at its default effort. The exception is the top: GPT-6.2 Astra and Fable 5.2 share a rate card, yet Astra reaches 62 for $2.52 a task because it finishes the index on far fewer tokens.
GPT-6.2 Astra and Sol: what changed?
Astra got cheaper and Sol got better. OpenAI’s GPT-6.2 Astra model page lists $8 input, $0.40 cached input and $40 output per million tokens, against GPT-6 Astra’s $10, $1 and $50. The GPT-6.2 Sol model page keeps GPT-6.1 Sol’s $2, $0.10 and $10. Both are in the API and in ChatGPT Work and Codex for paid plans from November 17, per OpenAI’s developer-forum announcement. On the Artificial Analysis index, Astra scores 62 at max for $4.00 a task and Sol 57 for $1.01, against 57 and $6.24 for GPT-6 Astra and 55 and $1.27 for GPT-6.1 Sol. The full reading is in GPT-6.2 Astra and Sol: pricing, benchmarks, cost per task.
Qwen4-Max: how much cheaper is it than Qwen3.8-Max?
25% on both lines. Alibaba’s Qwen4-Max model documentation lists $1.50 per million input tokens and $4.50 per million output on the international deployment, in a single tier all the way to the 1,000,000-token context, with thinking and non-thinking modes priced the same. Qwen3.8-Max launched at $2 and $6. Alibaba’s model release notes date qwen4-max to November 16; a preview had run inside Alibaba’s Token Plan since November 11. The independent Artificial Analysis index scores it 43 at $3.27 a task. It is proprietary: there are no Qwen4-Max weights.
Hy4 flash: what does Tencent’s cheapest model cost?
$0.07 per million input tokens and $0.281 per million output, with cache hits at $0.003, per Tencent Cloud’s price table, which also bills it at half price until November 30. That is roughly a twelfth of the full Hy4 on input. Hy4 flash is a mixture-of-experts model with 224 billion total parameters, 64 billion of them in Tencent’s Engram lookup memory, and 12 billion active per token, distilled from Hy4. The trade is coding: on Terminal-Bench 4.0 it scores 19.2 against Hy4’s 44.4, by Tencent’s own measure. Artificial Analysis has not scored it yet, and Tencent says the weights will be open-sourced later without giving a date.
Its parent, Hy4, shipped on November 4 per Tencent’s announcement, at $0.834 and $2.501 on Tencent Cloud (the press release rounds to about $0.90 and $2.70), with vision input and computer use. Artificial Analysis scores it 35. Tencent’s announcement calls it one of the leading open-source models, but its weights are not out either.
Gemini 4 Hydrogen: is it better than Gemini 4 Argon?
On the index, by a point, and it is cheaper. Google introduced Gemini 4 Hydrogen on November 12 at a flat $1.50 and $7.50 per million tokens across a 1-million-token window, and cites Artificial Analysis scores of 51 at its default high thinking level against 50 for Argon, rising to 54 at a new xhigh level. Argon sits at an introductory $2 and $10 that rises to $4 and $20 on December 1. Against Gemini 3.8 Flash, the model teams are most likely moving from, Google reports 57% on Terminal-Bench 4.1 against 18.2% and tasks finished about 2.5 times faster. It is on every Gemini API tier from day one, including the free tier in AI Studio.
Muse Ember: is it cheaper than Claude Haiku 5.5?
Per token, it is the same rate card: $0.10 input and $0.50 output, per Meta’s Muse Ember announcement, with prompts over 200,000 tokens billed at $0.30 and $1.50. It is Meta’s smallest Muse model, served as muse-ember-1.0 on the Meta Model API, with a 1-million-token context and up to 512,000 output tokens. On the Artificial Analysis v5 index it scores 36 at max effort, one point under Muse Spark 1.3, at $0.14 per index task against Spark’s $2.39. That makes it the cheapest scored model of the month by a wide margin.
Claude Fable 5.2: what changed?
The price. Anthropic released Claude Fable 5.2 and Claude Mythos 5.2 on November 9 at $8 and $40 per million tokens, 20% under Fable 5.1 on every line. It scores 62 on the Artificial Analysis index at its default high effort for $9.08 a task and 65 at max, the top score on the index. Mythos 5.2 is the same model without the cyber and biology safeguards, at the same price, for verified organizations only. The full reading is in Claude Fable 5.2: pricing, benchmarks, cost per task.
Inkling 2 Small: what does the open-weight option cost?
$0.30 input and $1.00 output per million tokens on Thinking Machines’ Tinker pricing page, against $1.20 output for the Inkling-Small it follows. Thinking Machines announced it on November 5 and published Apache 2.0 weights on November 12: 594 billion parameters, 17 billion active, with a 256,000-token context on Tinker. It scores 31 on the Artificial Analysis index, which makes it the only model in this month’s scored set you can download. Cognition’s SWE-2 Flash, released November 4 for Devin, is post-trained from the first Inkling-Small; Cognition reports 24.0% on FrontierCode 2.0 against 23.8% for SWE-2, and is holding its weights back.
What did OpenAI release in November 2026?
Five models. The two general models, GPT-6.2 Astra and GPT-6.2 Sol, arrived on November 17 (above). Before them came three specialist models. GPT Image 2.6 Flare and Sunburst arrived on November 4 per the OpenAI API changelog, adding SVG and animated GIF output at GPT Image 2.5’s unchanged $8 image input and $30 image output per million tokens. GPT-6 Cyber followed on November 5 for vulnerability research, open only to security teams in OpenAI’s trusted-access program, at $20 and $100 per million tokens for prompts up to 272,000 tokens, per OpenAI’s GPT-6 Cyber model page. That is double GPT-6 Astra’s standard rate and 2.5 times GPT-6.2 Astra’s. On October 30, OpenAI also shipped GPT-6 Rosalind for approved life-sciences teams at $15 and $75; it counts toward October.
Which decision model is cheapest now?
Celeris-1.1 Decision, by a factor of ten. Celeris lists it at $0.004 per million input tokens with output free, a tenth of Celeris-1 and of Perplexity’s pplx-decider-v1-27b. Google entered the category on November 11 with Gemini Decision 1 at $0.10 per million input tokens, output free, which is more per token than pplx-decider, Jev or Microsoft-Decision-1 (though under Cloudflare Clef’s $0.24), but takes text, images, audio, video and PDFs, and answers up to 1,000 questions per request in 150 to 250 milliseconds end to end. What a decision model is, and when one beats a small chat model, is covered in the October roundup.
Speech, image and video releases
ElevenLabs released Scribe v3 on November 10 at an unchanged $0.20 per audio hour, cutting its word error rate on the FLEURS benchmark from 16.94% to 12.38% across 102 languages, with a streaming Scribe v3 Live at $0.22 an hour. Google’s Gemini Omni 1.2 Flash on November 5 generates video at $0.07 per second of 720p, 30% below Omni 1.1 Flash, with clips up to 15 seconds; API calls to 1.1 move to 1.2 from December 3. MiniMax released the open-weight MiniMax H3-Image on November 11 without a USD price, and Baidu released ERNIE 5.5 Flash Preview the same day, priced in yuan only.
What happened to October’s models this month?
Several October launches changed status without counting as new releases. Google made Gemini 4 Carbon generally available on November 10 at its unchanged introductory $2 and $10, rising to $4 and $20 on December 1. Moonshot published the Kimi K3.1 Pro weights it had promised for November 4, Mistral’s model documentation now tags Mistral Large 4 generally available from November 5, and Reflection AI had already shipped Beam’s weights on October 16. Perplexity updated its open decision models to v1.3 on November 12, a version update this record does not count, the same rule applied to Jev 1.14 in October.
The release pace
November has twenty-two releases in seventeen days, already ahead of August’s full-month twelve. The release archive counts 5 tracked releases in June (from June 9, when the record starts), 21 in July, 12 in August, 34 in September and 25 in October. The month’s shape is a price war at both ends of the frontier: Hydrogen, Qwen4-Max and Muse Ember all launched under a model they compete with in the middle of the market, and at the top Fable 5.2 and GPT-6.2 Astra both launched 20% under their predecessors, on the same $8 and $40. Every output rate above $10 belongs to one of those two or to OpenAI’s specialists: two image models and a security model most teams cannot buy.
Several models appear on other November lists but not this one. HeyGen Decision 1 has documentation but no dated announcement or published price from HeyGen. ByteDance’s Seedream 5.5 has no dated first-party page. The November dates other trackers give for ERNIE-Light-DT-1.0, China Mobile’s JT-4.1 Flash and Z.ai’s GLM legal model are gateway listing dates, not lab announcements. A “DeepSeek V4.1 Flash 1017 Uncensored” is a third-party build, not a DeepSeek release, and a “GPT-6.1 Terra Pro” listing is a reasoning mode of Terra, not a new OpenAI model. Every date on this page is read off the lab’s own announcement or documentation. The method is set out in the AI model release archive.
Frequently asked questions
- What AI models were released in November 2026?
- As of November 18, 2026, twenty-two, from thirteen labs. OpenAI released GPT-6.2 Astra and GPT-6.2 Sol on November 17. Alibaba released Qwen4-Max and Tencent released Hy4 flash on November 16. Google released Gemini 4 Hydrogen on November 12 and Gemini Decision 1 on November 11, the day MiniMax released MiniMax H3-Image and Baidu released ERNIE 5.5 Flash Preview. ElevenLabs released Scribe v3 and Scribe v3 Live on November 10. Anthropic released Claude Fable 5.2 and Claude Mythos 5.2 and Meta released Muse Ember on November 9. On November 5 OpenAI released GPT-6 Cyber, Google released Gemini Omni 1.2 Flash, Thinking Machines released Inkling 2 Small and Celeris released Celeris-1.1 Decision. On November 4 Tencent released Hy4, Cognition released SWE-2 Flash, Ricursive Intelligence released Ripple-65B Preview and OpenAI released GPT Image 2.6 Flare and Sunburst.
- What is the cheapest AI model released in November 2026?
- Per token, Tencent Hy4 flash at $0.07 per million input tokens and $0.281 per million output, half that until November 30. It has no independent index score yet. Among scored models, Meta Muse Ember at $0.10 and $0.50 is the cheapest, scoring 36 on the Artificial Analysis index for $0.14 a task.
- Which November 2026 model is the best value?
- For cheap, high-volume work, Muse Ember: 36 on the Artificial Analysis index at $0.50 per million output tokens. For a mid-price model, Gemini 4 Hydrogen scores 51 at $1.50 and $7.50, above Gemini 4 Argon for less. Qwen4-Max scores 43 at $4.50 output if a Chinese proprietary model is allowed. At the top, GPT-6.2 Astra reaches 62 at xhigh effort for $2.52 a task, against $9.08 for the same score from Claude Fable 5.2 at its default high; Fable 5.2 alone reaches 65, at $26.54 a task.
- Is Hy4 flash open source?
- Not yet. Tencent says it will open-source Hy4 flash, but as of November 16, 2026 it has published no weights and no licence. The full Hy4 weights are also still pending; the only open Hy4 model is the earlier Hy4 Preview under Apache 2.0.
- How many AI models has the release archive tracked through November 2026?
- One hundred and nineteen dated launches from June 9, 2026: 5 in June, 21 in July, 12 in August, 34 in September, 25 in October and 22 in November as of November 18. Every row carries the price the model launched at and a link to the provider primary source.
Sources
Alibaba Cloud (2026). Qwen4-Max and Newly released models. Model Studio documentation: qwen4-max $1.50 / $4.50 per Mtok, one tier to 1,000,000 tokens, listed November 16, 2026. https://www.alibabacloud.com/help/en/model-studio/qwen4-max and https://www.alibabacloud.com/help/en/model-studio/newly-released-models Verified 2026-11-16.
Tencent Cloud (2026). TokenHub model pricing. Tencent Cloud documentation: hy4-flash $0.07 / $0.281, hy4 $0.834 / $2.501 per Mtok, launch discounts. https://www-sg.tencentcloud.com/zh/document/product/1300/78937 Verified 2026-11-16.
Tencent (2026). Tencent launches Hy4, joining the ranks of the world’s leading open-source AI models. Press release, November 4, 2026. https://www.tencent.com/tencent-launches-hy4-joining-the-ranks-of-the-worlds-leading-open-source-ai-models/ Verified 2026-11-16.
Google (2026). Introducing Gemini 4 Hydrogen. Company announcement, November 12, 2026: $1.50 / $7.50 per Mtok, Artificial Analysis scores, Terminal-Bench 4.1. https://blog.google/innovation-and-ai/models-and-research/gemini-models/introducing-gemini-4-hydrogen/ Verified 2026-11-16.
Google (2026). Gemini 4 Carbon is now available. Company announcement, November 10, 2026. https://blog.google/innovation-and-ai/models-and-research/gemini-models/gemini-4-carbon-now-available/ Verified 2026-11-16.
Google (2026). Gemini Decisions API. Company announcement, November 11, 2026: gemini-decision-1 at $0.10 per Mtok input, output free. https://blog.google/innovation-and-ai/technology/developers-tools/gemini-decisions-api/ Verified 2026-11-16.
Google (2026). Introducing Gemini Omni 1.2 Flash. Company announcement, November 5, 2026. https://blog.google/innovation-and-ai/technology/developers-tools/introducing-gemini-omni-1-2-flash/ Verified 2026-11-16.
Meta (2026). Muse Ember. Meta research blog, November 9, 2026: $0.10 / $0.50 per Mtok, 1M context. https://research.meta.ai/blog/muse-ember Verified 2026-11-16.
OpenAI (2026). GPT-6.2 Astra and GPT-6.2 Sol model documentation, and GPT-6.2 Astra and Sol are now available, OpenAI Developer Community announcement, November 17, 2026. https://developers.openai.com/api/docs/models/gpt-6.2-astra, https://developers.openai.com/api/docs/models/gpt-6.2-sol and https://community.openai.com/t/gpt-6-2-astra-and-sol-are-now-available/1417531 Verified 2026-11-18.
Anthropic (2026). Claude Fable 5.2 and Claude Mythos 5.2. Company announcement, November 9, 2026. https://www.anthropic.com/claude-fable-and-mythos-5-2 Verified 2026-11-10.
OpenAI (2026). API changelog, API pricing and GPT-6 Cyber model documentation. GPT Image 2.6 (November 4), GPT-6 Cyber (November 5) and GPT-6 Rosalind (October 30) rates. https://developers.openai.com/api/docs/changelog, https://developers.openai.com/api/docs/pricing and https://developers.openai.com/api/docs/models/gpt-6-cyber Verified 2026-11-16.
Thinking Machines (2026). Inkling 2 Small and Tinker pricing. Company announcement, November 5, 2026, and pricing page: $0.30 / $1.00 per Mtok, 256K context. https://thinkingmachines.ai/news/inkling-2-small/ and https://thinkingmachines.ai/tinker/pricing/ Verified 2026-11-16.
Cognition (2026). Introducing SWE-2 Flash and Devin models. Company blog, November 4, 2026, and Devin documentation with promotional and list rates. https://cognition.com/blog/swe-2-flash and https://docs.devin.ai/desktop/models Verified 2026-11-16.
Ricursive Intelligence (2026). Ripple. Model page for Ripple-65B Preview, Apache 2.0. https://www.ricursive.com/ripple Verified 2026-11-16.
Celeris (2026). Celeris-1.1 Decision. Model page: $0.004 per Mtok input, output free. https://celeris.ai/celeris-1-1-decision Verified 2026-11-16.
ElevenLabs (2026). Scribe v3. Company blog, November 10, 2026. https://elevenlabs.io/blog/scribe-v3 Verified 2026-11-16.
MiniMax (2026). MiniMax H3-Image. Company blog, November 11, 2026. https://www.minimax.io/blog/minimax-h3-image Verified 2026-11-16.
Baidu (2026). ERNIE 5.5 Flash Preview. Release page, November 11, 2026. https://ernie.baidu.com/release/ernie-5-5-flash-preview/ Verified 2026-11-16.
Artificial Analysis (2026). Qwen4 Max, Muse Ember, Tencent Hy4, Gemini 4 Hydrogen, GPT-6.2 Astra and GPT-6.2 Sol model pages. Independent Intelligence Index v5.0.1 scores and cost per index task. https://artificialanalysis.ai/models/qwen4-max, https://artificialanalysis.ai/models/muse-ember, https://artificialanalysis.ai/models/tencent-hy4, https://artificialanalysis.ai/models/gemini-4-hydrogen, https://artificialanalysis.ai/models/gpt-6-2-astra and https://artificialanalysis.ai/models/gpt-6-2-sol Read 2026-11-16 (GPT-6.2 pages 2026-11-18).