New AI Models Released in October 2026: Prices
Every AI model released in October 2026, with dates, verified launch prices and a primary source for each. Updated through the month as releases land.
Twenty-five AI models were released in October 2026, from seventeen labs. The last was OpenAI’s GPT-6 Rosalind on October 30, a life-sciences model for approved research teams at $15 and $75 per million tokens. Before it came Google’s Gemini 4 Carbon on October 28, its strongest model and first on the new Artificial Analysis v5 index at 59, though only cyber defenders in Google’s Fairwind Program can use it so far. Before it came OpenAI’s GPT-6.1 Terra on October 26, OpenAI’s first release of the month, at $1 and $5 per million tokens, half the GPT-6.1 Sol rate card, scoring 48 on the independent Artificial Analysis index for $0.40 a task, under a third of what the GPT-5.6 Terra it replaces cost. Three days earlier came Moonshot’s Kimi K3.1 Pro on October 23, at $2 and $10 per million tokens, a third below the Kimi K3 it replaces, scoring 55 on the independent Artificial Analysis index, fourth of any model and the top score of any model with weights promised (by November 4). Four days earlier MiniMax released the open-weight MiniMax-M3.1-Flash at $0.15 and $0.60, and on October 17 DeepSeek swapped a stronger build of V4.1 Flash in behind the same API name at the same price. Meta’s Muse Spark Open on October 15 is an 816-billion-parameter open-weight model that third-party hosts serve at $1.25 and $4.25 per million tokens and that scores 39, the top US open-weight score. The biggest is Meta’s Muse Wonder on October 12, its first frontier-tier model, at $4 and $20 per million tokens, the same rate card as Claude Opus 5.5, with a larger Muse Wonder Full sold only inside Meta’s Muse Code plans. Before it came Anthropic’s Claude Haiku 5.5 on October 7 at $0.10 and $0.50, a tenth of Haiku 4.5, and two open-weight contenders, Mistral Large 4 (a half-price public preview on October 6) and Reflection AI’s Beam (announced October 5, waitlist only). Google shipped Nano Banana 2.1, and on October 9 Microsoft added a decision model and Alibaba a faster image model. None came from xAI.
Ten of the twenty-five landed on October 1, and their headline is a new kind of model: Cloudflare, AWS Strands Labs and Perplexity each shipped an open decision model that answers with probabilities instead of text, bills input only and charges nothing for output. The cheapest is Perplexity’s pplx-decider-v1-27b at $0.04 per million input tokens. The same day brought Microsoft’s MAI speech trio, Black Forest Labs’ FLUX 3 Image, a gated Tavus video preview, and the month’s only price cut so far, Unbiased’s Pareto 26.10 Preview.
The quick verdict for anyone choosing today: Kimi K3.1 Pro is the cheapest model within three points of the top of the independent index, at $2.11 a task against $5.98 for Claude Opus 5.5. For mid-tier agent and computer-use work on OpenAI, GPT-6.1 Terra at $0.40 a task is the new default to test before paying 1.8 times as much for GPT-6.1 Sol’s four extra points. Muse Wonder is worth a trial only for long-running coding agents, since GPT-6.1 Sol reaches the same independent score for a sixth of the cost per task. For cheap, high-volume text work (summaries, classification, subagents), Claude Haiku 5.5 is the new default to test, at GPT-6 Luna’s rate card with a higher independent score, and DeepSeek’s October 17 build of V4.1 Flash scores two points more for $0.26 a task if a Chinese model is allowed. For a yes or no, label or routing call, pplx-decider-v1-27b is the cheapest managed option and is open-weight, and Clef-flash wins when latency matters more than price. Neither Mistral Large 4 nor Beam can be downloaded yet; both promise weights before November. Muse Spark Open can, today, though Q4 weights need more memory than one 512GB Mac Studio holds.
Every AI model released in October 2026
| Model | Provider | Released | Launch price | What it is |
|---|---|---|---|---|
| pplx-decider-v1-27b | Perplexity | Oct 1 | $0.04 input / $0 output per Mtok | Open decision model behind the Perplexity Decisions API. Apache 2.0 |
| Clef | Cloudflare | Oct 1 | $0.24 input / $0 output per Mtok | Cloudflare’s first in-house model. Open decision model on Workers AI |
| Clef-flash | Cloudflare | Oct 1 | $0.09 input / $0 output per Mtok | Latency tier of Clef: 38.8 ms median decision. Apache 2.0 |
| Strands Decider 2B | AWS Strands Labs | Oct 1 | Self-hosted, no rate | 2B open decision model that runs locally, training recipe published |
| Pareto 26.10 Preview | Unbiased | Oct 1 | $0.80 / $3.20 per Mtok | Preview of the next Pareto blend, 68% below Pareto 26.9 on input |
| MAI-Transcribe-2-Streaming | Microsoft | Oct 1 | $0.54 per audio hour (introductory) | Microsoft’s first streaming speech-to-text model |
| MAI-Voice-2.1 | Microsoft | Oct 1 | $22 per million characters | Text-to-speech in 23 languages and 26 locales |
| MAI-Voice-2.1-Flash | Microsoft | Oct 1 | $15 per million characters | Low-latency text-to-speech tier, about 150 ms end to end |
| FLUX 3 Image | Black Forest Labs | Oct 1 | $0.041 to $0.607 per image | Image generation and editing half of FLUX 3, up to 4K and ten references |
| Griffin-Lite | Tavus | Oct 1 | Not published | Full-duplex video-to-video research preview, invited testers only |
| Beam | Reflection AI | Oct 5 | Not published | 501B open-weight MoE (23B active), waitlist only, Apache 2.0 weights due |
| Nano Banana 2.1 | Oct 6 | $0.0336 per 1K image | Image generation and editing, image output half Nano Banana 2’s rate | |
| Mistral Large 4 | Mistral | Oct 6 | $0.68 / $2.09 per Mtok (launch sale) | 1.05T open-weight MoE preview, standard $1.36 / $4.18, weights due Oct |
| Claude Haiku 5.5 | Anthropic | Oct 7 | $0.10 / $0.50 per Mtok (under 100K) | Anthropic’s small tier, 90% below Haiku 4.5, $0.50 / $2.50 over 100K |
| Microsoft-Decision-1 | Microsoft | Oct 9 | $0.042 input / $0 output per Mtok | Decision model on Microsoft Foundry, post-trained from Qwen3.5-9B |
| Qwen-Image-2.1-Turbo | Alibaba | Oct 9 | $0.014 per image | 8-step distilled Qwen-Image-2.1, weights under a research licence |
| Muse Wonder | Meta | Oct 12 | $4 / $20 per Mtok | Meta’s first frontier-tier model, API preview, scores 52 on the AA index |
| Muse Wonder Full | Meta | Oct 12 | Muse Code plans only ($50 and up) | The larger Wonder, no API, scores 56 on the AA index |
| Muse Spark Open | Meta | Oct 15 | $1.25 / $4.25 per Mtok (hosts) | 816B open-weight MoE (42B active), Muse Model License, 39 on the AA index |
| DeepSeek V4.1 Flash 1017 | DeepSeek | Oct 17 | $0.30 / $1.20 per Mtok (peak) | In-place update behind deepseek-flash, same price, AA index 39 to 45 |
| MiniMax-M3.1-Flash | MiniMax | Oct 19 | $0.15 / $0.60 per Mtok | 428B open-weight MoE (23B active), 43 on the AA index |
| Kimi K3.1 Pro | Moonshot | Oct 23 | $2 / $10 per Mtok | Post-trained K3, 55 on the AA index, weights due Nov 4 |
| GPT-6.1 Terra | OpenAI | Oct 26 | $1 / $5 per Mtok | Replaces GPT-5.6 Terra at half of Sol’s rate, 48 on the AA index |
| Gemini 4 Carbon | Oct 28 | $2 / $10 per Mtok (introductory) | Google’s strongest model, Fairwind only, 59 on the AA v5 index | |
| GPT-6 Rosalind | OpenAI | Oct 30 | $15 / $75 per Mtok (up to 272K) | Life-sciences model for approved Enterprise research teams only |
GPT-6 Rosalind: who can use it?
Only organizations OpenAI approves for life-sciences research. The OpenAI API changelog dates GPT-6 Rosalind to October 30, “bringing specialized biological reasoning with scientific tool use to complex life sciences research”, with access through its trusted-access program. OpenAI’s pricing page lists $15 per million input tokens and $75 output for prompts up to 272,000 tokens, and $30 and $112.50 above that: 1.5 times GPT-6 Astra on both lines. No independent index score has been published.
Gemini 4 Carbon: can you use it yet?
Only if you are a cyber defender in Google’s Fairwind Program. Google announced Gemini 4 Carbon on October 28 as “our strongest model”, two weeks after Gemini 4 Argon opened to every paid developer, and gave developers, businesses and consumers no date beyond “as soon as possible”. The rate card is Argon’s: an introductory $2 and $10 per million tokens, then $4 and $20, with no end date for the introductory period. On the independent Artificial Analysis index it ranks first at 59, one point ahead of Claude Opus 5.5, at $7.76 per index task at the standard rate. That score is on the v5 scale Artificial Analysis launched on October 27, so it does not compare with the earlier-scale index figures elsewhere on this page. The full reading is in Gemini 4 Carbon: pricing, benchmarks, access.
GPT-6.1 Terra: how much cheaper is it than GPT-6.1 Sol?
Per token, exactly half: $1 per million input tokens, $5 per million output and $0.05 cached, against GPT-6.1 Sol’s $2, $10 and $0.10, per OpenAI’s GPT-6.1 Terra model documentation. Per task, less than half the saving. The independent Artificial Analysis index measures $0.40 per index task at max effort against $0.72 for Sol, because Terra spends 130 million output tokens on the run where Sol spends 67 million. For that 56% of the cost it scores 48 against Sol’s 52, and 6 points above the GPT-5.6 Terra it replaces, which AA puts at $1.40 a task.
OpenAI released it on October 26 in the API as gpt-6.1-terra and in ChatGPT Work and Codex for Plus, Pro, Enterprise and Edu users, pitched at computer use: reading a screen and acting across apps. Its launch figures (50.3% on Terminal-Bench 4.0 against 21.5% for GPT-5.6 Terra, more than three times faster than Astra and Sol) are vendor-reported and not yet on the independent board. The full cost-per-task comparison against Sol, Claude Haiku 5.5 and Kimi K3.1 Pro is in GPT-6.1 Terra: pricing, benchmarks, cost per task.
Kimi K3.1 Pro: is it cheaper than Kimi K3?
Per token, yes, by a third: $2 per million input tokens, $10 per million output and $0.20 cached, against K3’s $3, $15 and $0.30, per the Kimi API pricing page. Per task, no. The independent Artificial Analysis index measures $2.11 per index task against $2.00 for K3, because the new model spends about 14% more output tokens on each one. What the same money buys is the change: 55 points against 44, fourth of any model, behind only Claude Opus 5.5 (58), Claude Sonnet 5.5 and Muse Wonder Full (56).
Moonshot released K3.1 Pro on October 23 as a post-trained K3, 2.8 trillion parameters with 104 billion active and a 1M-token context, live the same day on the Kimi API and apps. A Highspeed variant runs two to three times faster at $4 and $20. The weights are promised by November 4; until they ship, Artificial Analysis lists it as proprietary. The cost-per-task comparison against Opus 5.5 and Gemini 4 Argon is in Kimi K3.1 Pro: pricing, benchmarks, open weights.
MiniMax-M3.1-Flash: how cheap is a 43?
$0.15 per million input tokens, $0.60 output and $0.015 for a cache read, flat, per MiniMax’s pricing overview. MiniMax lists it as released on October 19 in its model release notes, with weights on Hugging Face: about 428 billion parameters, 23 billion active, a 1M-token context and text, image and video input. The licence asks for a “Built with MiniMax M3.1-Flash” credit and written approval above $20 million a year in revenue.
The independent Artificial Analysis index scores it 43 for $0.22 a task, the same score as Claude Haiku 5.5 for one cent more, and 14 points above MiniMax-M3. Artificial Analysis still lists the weights as unavailable; the Hugging Face repository says otherwise.
DeepSeek V4.1 Flash 1017: what changed?
The model, not the price. DeepSeek shipped DeepSeek-V4.1-Flash-1017 on October 17 as an in-place update: deepseek-flash now serves it, and its change log says the calling method and pricing are unchanged, so peak rates stay $0.30 input and $1.20 output per million tokens, half that off-peak. The Artificial Analysis index moves it from 39 to 45 at max effort, for $0.26 a task. That ties GLM-5.3 at an eighth of GLM’s $2.01. Weights are MIT-licensed on Hugging Face. DeepSeek also added paid Search and Fetch APIs at $0.75 per 1,000 calls.
Muse Wonder: what does Meta’s first frontier model cost?
$4 per million input tokens and $20 per million output, with a $0.20 cached input and no long-context premium, per the Meta Model API pricing page. That is the Claude Opus 5.5 rate card exactly, and 3.2 times what Muse Spark 1.3 charges for input. Meta released Muse Wonder and Muse Wonder Full on October 12. Wonder is a self-serve API preview open to anyone today; Wonder Full has no API and runs only inside Muse Code, on the $50 and $200 plans, according to Meta’s model documentation.
The independent Artificial Analysis index scores Wonder 52 at max effort for $4.52 a task and Wonder Full 56, fourth of 689 models. Opus 5.5 scores 58 for $5.98 at the same per-token price, while GPT-6.1 Sol scores 52 for $0.72. Meta’s own model card has Wonder ahead of Opus 5.5 on long-horizon coding (SWE-Marathon, DeepSWE) and behind it on Terminal-Bench, ProgramBench and OSWorld; all vendor-reported. The breakdown, including Muse Code’s default-on training setting, is in Muse Wonder: pricing, benchmarks, cost per task.
Muse Spark Open: what does Meta’s open-weight model cost?
$1.25 per million input tokens and $4.25 per million output, with a $0.15 cached input, from every host that serves it. Meta runs no API for it: the price is what Modal, Together, Nebius, Fireworks and Baseten all list on OpenRouter’s Muse Spark Open page, and it is the same rate card as Meta’s closed Muse Spark 1.3. Meta released Muse Spark Open on October 15 with weights on Hugging Face: 816 billion parameters, 42 billion active per token, a 1M-token context, and text, image, video and audio input.
The independent Artificial Analysis index scores it 39 at xhigh effort for $0.84 a task. That is nine points below Muse Spark 1.3 at the same price per token, and level with the September build of DeepSeek V4.1 Flash, which reached 39 for $0.27 before DeepSeek’s October 17 update lifted it to 45. Every open-weight model above it on that index comes from a Chinese lab. The licence is Meta’s own Muse Model License, which requires a visible credit and a separate deal for model-API businesses above $20 million in revenue. The hardware math and the full comparison are in Muse Spark Open: pricing, benchmarks, hardware.
Claude Haiku 5.5: is it cheaper than GPT-6 Luna?
Per token, no: it is the same price. Anthropic released Claude Haiku 5.5 on October 7 at $0.10 input and $0.50 output per million tokens with a $0.01 cache read, the identical rate card to GPT-6 Luna, but only for prompts up to 100,000 tokens. Above that line every token in the request costs five times as much, $0.50 and $2.50, per Anthropic’s pricing documentation. Anthropic says prompts under the line made up about 90% of Haiku 4.5 requests, and that the new model runs about 75% cheaper than Haiku 4.5 overall (Anthropic’s Haiku 5.5 announcement).
What separates it from Luna is the score. The independent Artificial Analysis Intelligence Index puts Haiku 5.5 at 43 at max effort for $0.21 a task, against 38 and $0.07 for Luna: five points more for three times the per-task cost. The same launch halved the Sonnet 5.5 cache read to $0.10, which made Sonnet 5.5 cheaper per task than Opus 5.5 at max effort. The full breakdown, including where the 100K line flips the comparison, is in Claude Haiku 5.5: pricing, benchmarks, cost.
Mistral Large 4: what does Europe’s biggest open model cost?
Mistral opened a public preview of Mistral Large 4 on October 6: a 1.05-trillion-parameter mixture-of-experts model with 52 billion active parameters, image input and a 1M-token context, per Mistral’s model documentation. The preview API is on a launch sale at $0.68 input and $2.09 output per million tokens, half the standard $1.36 and $4.18, and Mistral gives no end date for the sale. The weights arrive “by the end of the month,” according to Mistral’s announcement, which does not yet name a licence.
Artificial Analysis scores the preview 38, level with GPT-6 Luna and below the cheaper Chinese open models GLM-5.3 (45) and Kimi K3 (44). Mistral’s case rests on cybersecurity, where it reports 93% on Cybench, on visual grounding and on European hosting. The analysis is in Mistral Large 4: pricing, benchmarks, open weights.
Reflection AI Beam: can you use it yet?
Not unless you are on the waitlist. Reflection AI announced Beam on October 5, a text-only model with 501 billion total and 23 billion active parameters, in its post Introducing Beam. There is no public API and no price. Reflection says the weights, technical report and model card ship under Apache 2.0 later in October. On Reflection’s own table Beam is roughly level with GLM-5.2 and behind GLM-5.3, Kimi K3 and Qwen 3.8 Max on coding; its pitch is that it gets there with far fewer active parameters. Every score is vendor-reported. The breakdown is in Reflection AI Beam: benchmarks, open weights, access.
Nano Banana 2.1: did Google cut the image price?
On images, yes. Google released Nano Banana 2.1 (gemini-nano-banana-2.1) on October 6 as the update to Nano Banana 2, and deprecated the older model with no shutdown date, per the Gemini API release notes. The Gemini API pricing page lists image output at $30 per million tokens, half Nano Banana 2’s $60, which works out to $0.0336 for a 1K image against $0.067, and $0.113 at 4K against $0.151. Input went the other way, from $0.50 to $1.50 per million tokens, and text output from $3 to $7.50. For a short prompt that returns an image, the new model costs about half as much. For long reference-heavy edits the higher input rate eats into that.
Gemini 4 Argon: can every developer use it now?
Yes, since October 13. Google rolled Gemini 4 Argon out globally to the paid Gemini API tier, enterprise customers, Antigravity, and Google AI Pro and Ultra subscribers in the Gemini app. It is not a new October release: Argon shipped on September 30 to cyber defenders only and is counted in September’s list. What October adds is the end date. The Gemini API pricing page holds the introductory $2 and $10 per million tokens through November 30, then charges $4 and $20 from December 1, so Argon’s cost-per-task lead over GPT-6 Astra lasts seven weeks. The full reading is in the Gemini 4 Argon breakdown.
What is a decision model, and why did three ship on one day?
A decision model does not write. You send it the state of your application and a typed question (yes or no, pick one of these options, place this on a scale), and it returns one answer with a probability attached to every option. There is no free text to parse, so the output cannot drift out of format, and the probability lets you set a threshold and send the unsure cases to a person or a larger model.
The category was defined by TypeSafe’s Jev, which charges $0.042 per million input tokens and nothing for output; the full breakdown is in what Jev is and what it costs. October 1 is the day the format stopped being one company’s product. Three open alternatives shipped within hours of each other:
- Clef and Clef-flash, Cloudflare’s first models trained in-house, announced in the Cloudflare blog post Clef: open decision models under Apache 2.0. Cloudflare reports a median decision time of 209.3 ms for Clef and 38.8 ms for Clef-flash, with 238.6 ms and 122.4 ms at the 95th percentile. Both take a 65,536-token context, per the Workers AI model documentation.
- Strands Decider 2B, from AWS’s Strands Labs, described in Introducing Strands Decider 2B. It takes a Qwen 2B base and replaces the next-word head with a pointer head of just over a million parameters that scores your options. Strands reports a median of about 115 ms on an Nvidia RTX 3090 and 153 ms on a MacBook M3, and ships the training data and scripts alongside the weights.
- pplx-decider-v1-27b, Perplexity’s model behind its new Decisions API, fine-tuned from Qwen3.8-27B and published on Hugging Face under Apache 2.0. Perplexity’s own model card reports 85.71% across 11 benchmarks, against 74.76% for the base model it started from. That is a vendor-run comparison, not an independent one.
The wave did not start on October 1. Three closed decision models launched in the last two days of September: Liquid AI’s d1 on September 29 (as reported by MarkTechPost), and Inception’s Mercury Decide and Fastino’s GLiDE on September 30. They are September releases by their own dates, which is why they are not in the October table. What October 1 added was open weights: all three October 1 decision models can be downloaded and run on your own hardware. A fourth arrived closed on October 9: Microsoft-Decision-1 on Microsoft Foundry, post-trained from Qwen3.5-9B, at $0.042 per million input tokens with output not billed, the same rate as Jev, per Microsoft’s Foundry announcement.
Jev itself moved on October 14. TypeSafe released jev-1.14.0 at the unchanged $0.042 rate under its jev-preview alias, with experimental image input (PNG or JPEG, billed as ordinary input tokens) and a new Box answer type that returns a bounding box, both behind opt-in headers that TypeSafe says are not ready for production, per its Jev 1.14 announcement. It is a version update to a September model rather than a new one, so it is not counted in the October table; the limits and caveats are in can Jev read images.
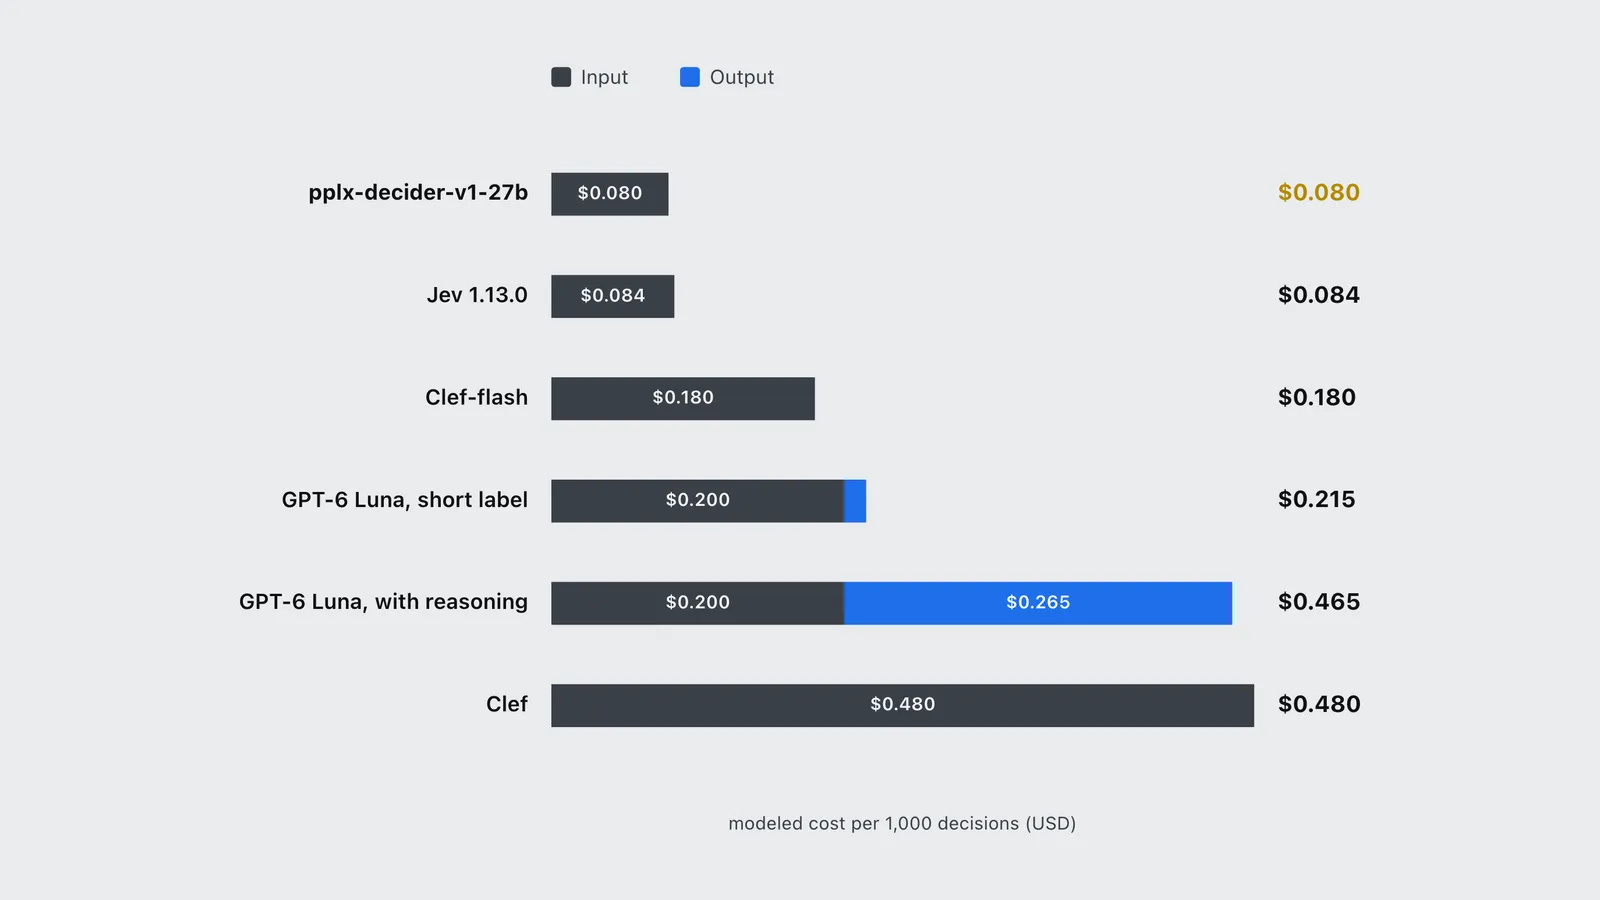
Is a decision model cheaper than a small chat model?
Only some of them, and the free output matters less than it sounds. A chat model asked for a one-word label writes very little, so its output bill is small. The input rate decides the cost, and on input, Clef is more expensive than the cheapest chat tier on the market.
| Scenario | Input | Output | Total |
|---|---|---|---|
| pplx-decider-v1-27b | $0.080 | $0.000 | $0.080 |
| Jev 1.13.0 | $0.084 | $0.000 | $0.084 |
| Clef-flash | $0.180 | $0.000 | $0.180 |
| GPT-6 Luna, short label | $0.200 | $0.015 | $0.215 |
| GPT-6 Luna, with reasoning | $0.200 | $0.265 | $0.465 |
| Clef | $0.480 | $0.000 | $0.480 |
The model behind the chart is simple and every input is a list price. Each decision sends 2,000 tokens of state and question. GPT-6 Luna, OpenAI’s cheapest tier at $0.10 input and $0.50 output per million tokens on the OpenAI API pricing page, is costed two ways: answering with a 30-token label, and answering after about 500 tokens of reasoning.
Three things follow from it:
- pplx-decider and Jev are the only clear price wins. At $0.04 and $0.042 per million input tokens they cost less than half of a short-label Luna call, and the gap widens as soon as the chat model reasons.
- Clef-flash roughly ties a short-label Luna call ($0.180 against $0.215). Its case is speed and the probability on every answer, not a lower bill.
- Clef costs more than a short-label Luna call and about the same as a Luna call that reasons. Pick it for the calibrated probabilities, the open weights and staying inside Cloudflare’s network, not for price.
The chart leaves out what a decision model does not do: it cannot explain itself, write a reply or call a tool. The comparison holds only for jobs that end in a choice.
Which October decision model should you pick?
- Cheapest managed calls: pplx-decider-v1-27b at $0.04 per million input tokens, with images accepted alongside text.
- Lowest latency on a hosted API: Clef-flash, at a 38.8 ms median by Cloudflare’s measurement, already inside Workers AI if your app runs there.
- On your own hardware or offline: Strands Decider 2B. At 2B parameters it runs on a laptop GPU, and Strands ships the training data and scripts with the weights.
- Already on Azure: Microsoft-Decision-1 at $0.042, inside Foundry, if keeping traffic on one cloud matters more than shaving the rate.
- Already on Jev: there is no price reason to move. Jev’s $0.042 is within a fraction of a cent of pplx-decider per thousand calls, so test the accuracy on your own questions before switching.
How to get started with a decision model
- Pick five to ten decisions your app already makes with a chat model and a parsing step: ticket routing, moderation, a yes or no gate before a tool call.
- Log the inputs and the chat model’s answers for a few hundred real cases. That log is your test set.
- Run the same cases through pplx-decider-v1-27b or Clef-flash and compare agreement and the probability spread. Set a threshold below which the case falls back to the chat model.
- Price the switch with the chart’s method: your real input tokens per call times the input rate, against your current per-call bill.
Pareto 26.10 Preview: the first price cut of October
Two weeks after Pareto 26.9 launched at $2.50 and $7.50 per million tokens, Unbiased published a preview of its successor at $0.80 input, $0.03 cached input and $3.20 output, according to the Unbiased model card. That is 68% less on input and 57% less on output than the model it previews. The only benchmark published so far is Unbiased’s own, preliminary and vendor-run: 69.9% on DeepSWE v1.1 at $0.24 per task. Unbiased says the figures may change before final publication and that its cost method still needs confirming.
Treat the price as a preview price. Unbiased’s own listing on OpenRouter describes the model as a preview of the next Pareto version and points stable workloads at Pareto 26.9.
Microsoft MAI speech models: what does $0.54 an hour buy?
Microsoft shipped three speech models on October 1, all generally available, per its announcement Our first streaming transcription model debuts at no. 1 on Artificial Analysis:
- MAI-Transcribe-2-Streaming transcribes speech as it arrives, in 60 languages. Microsoft cites the independent Artificial Analysis AA-WER Streaming evaluation, where it ranks first at a 2.5% word error rate with the final transcript ready 0.13 seconds after the speaker stops. It costs $0.54 per audio hour at an introductory rate that runs through the end of 2026.
- MAI-Voice-2.1 is text-to-speech across 23 languages and 26 locales at $22 per million characters, and keeps a single voice natively accented in every language.
- MAI-Voice-2.1-Flash generates 45 seconds of audio at about 150 ms end-to-end latency for $15 per million characters, 32% less than the full model.
The streaming transcriber is the one to watch for cost. A voice agent pays for every second of audio the caller speaks, so the year-end expiry of the introductory rate is a date to put in the budget now, not in January.
FLUX 3 Image: what does an image cost?
Black Forest Labs announced FLUX 3 in July as one network for image, video, audio and robot actions. FLUX 3 Image is the image half reaching the API, dated October 1 in the Black Forest Labs release notes. It takes up to ten reference images, places elements by bounding box and renders in 15 aspect ratios. Pricing is per image, by resolution:
| Resolution | Price per image |
|---|---|
| 768 square | $0.041 |
| 1K | $0.048 |
| 2K | $0.100 |
| 4K | $0.607 |
The step to 4K is the one to notice: a 4K image costs six times a 2K one.
Tavus Griffin-Lite: a video model you cannot buy yet
Tavus describes Griffin as a full-duplex video-to-video model: it watches, listens and replies in speech and video at once, rather than passing a call through separate speech, language and video systems. Only the smaller Griffin-Lite is out, as a research preview for invited testers, per the Tavus Griffin page. The full model is held back until safety concerns are addressed. Tavus reports a score of 3.83 out of 5 on NVIDIA’s VideoFDB generation benchmark, against a human reference of 3.92 and 2.80 for the next system. In a company-run test, 26 of 54 people (48%) believed after a one-minute call that they had been talking to a real person. No price is published.
The release pace
October closed with twenty-five releases, ten of them on October 1. For comparison, the release archive counts 5 tracked releases in June (from June 9, when the record starts), 21 in July, 12 in August and 34 in September. October opened without a frontier launch: the largest models of the first week, Mistral Large 4 and Beam, are open-weight contenders rather than new leaders, and Anthropic’s release was its smallest tier. The first frontier-tier release came on October 12, and it came from Meta, not from OpenAI, Google or Anthropic. Three days later Meta also shipped the month’s largest downloadable model so far, Muse Spark Open. The second frontier-tier release came from China: Moonshot’s Kimi K3.1 Pro on October 23, at about a third of the per-task cost of the model that still tops the independent index. OpenAI’s first October release came three days later, and it was a price move rather than a new leader: GPT-6.1 Terra halves the mid tier. The new leader came two days after that from Google: Gemini 4 Carbon tops the independent index, behind the same Fairwind gate Argon launched behind.
Several models appear on other October lists but not this one, because their own announcements date them elsewhere. Liquid d1, Mercury Voice and Mercury Decide, GLiDE, Ant Group’s Ling-3.1-flash and Bilibili’s Index-Translate all launched on September 29 or 30. Apodex 1.1 Mini appears as an October 1 release on one gateway, but its weights shipped with Apodex 1.1 at the start of September; October 1 is when the gateway listed it. GPT-Synopsys, announced by OpenAI and Synopsys on September 30, is a partnership to build a chip-design model, not a model anyone can use yet. Every date on this page is read off the lab’s own announcement or documentation. The method is set out in the AI model release archive.
Did OpenAI release a new model in October 2026?
Yes, two. The general one is GPT-6.1 Terra on October 26, at $1 input and $5 output per million tokens, replacing GPT-5.6 Terra as the mid tier between GPT-6 Luna and GPT-6.1 Sol; the breakdown is in GPT-6.1 Terra: pricing, benchmarks, cost per task. The other is GPT-6 Rosalind on October 30, a life-sciences model at $15 and $75 for approved research organizations only. Before it, OpenAI’s most recent release was GPT-6.1 Sol, shipped at DevDay on September 29 at $2 input and $10 output with the cache read halved to $0.10, and its cheapest tier, GPT-6 Luna at $0.10 and $0.50, launched on September 22. Both are covered in the September roundup, and current rates for every OpenAI model are in the AI model tracker.
Did Google or Anthropic release a new model in October 2026?
Both did. Anthropic’s release was its small tier, and Google’s new flagship is one most readers cannot use yet. Anthropic released Claude Haiku 5.5 on October 7, its small tier, at $0.10 and $0.50 per million tokens for prompts up to 100,000 tokens, and halved the Sonnet 5.5 cache read the same day. Google released the image model Nano Banana 2.1 on October 6. Google’s newest language model is Gemini 4 Carbon, announced on October 28 for Fairwind cyber defenders only, with no public date. The newest one any developer can call is still Gemini 4 Argon, released on September 30 to cyber defenders in its Fairwind Program and opened to every paid Gemini API developer on October 13, at an introductory $2 and $10 per million tokens through November 30 and $4 and $20 from December 1; the detail is in the Gemini 4 Argon breakdown.
Frequently asked questions
- What AI models were released in October 2026?
- Twenty-five. OpenAI released GPT-6 Rosalind on October 30 for approved life-sciences teams at $15 and $75 per million tokens. Google announced Gemini 4 Carbon on October 28, its strongest model, for Fairwind cyber defenders only, at an introductory $2 and $10 per million tokens. OpenAI released GPT-6.1 Terra on October 26 at $1 and $5 per million tokens, half the GPT-6.1 Sol rate. Moonshot released Kimi K3.1 Pro on October 23 at $2 and $10 per million tokens, MiniMax released the open-weight MiniMax-M3.1-Flash on October 19 at $0.15 and $0.60, and DeepSeek replaced V4.1 Flash with its October 17 build at unchanged rates. Meta released the open-weight Muse Spark Open on October 15, served by third-party hosts at $1.25 and $4.25 per million tokens. Meta released Muse Wonder on October 12 as an API preview at $4 and $20 per million tokens, with Muse Wonder Full available only in its Muse Code plans. On October 9 Microsoft released the decision model Microsoft-Decision-1 at $0.042 per million input tokens and Alibaba released Qwen-Image-2.1-Turbo at $0.014 an image. Anthropic released Claude Haiku 5.5 on October 7 at $0.10 and $0.50 per million tokens for prompts up to 100,000 tokens. Mistral opened a public preview of Mistral Large 4 on October 6 at a launch-sale $0.68 and $2.09, and Google released the image model Nano Banana 2.1 the same day. Reflection AI announced the open-weight Beam on October 5 with waitlist access only. The other ten landed on October 1: Perplexity released pplx-decider-v1-27b at $0.04 per million input tokens with free output; Cloudflare released Clef at $0.24 and Clef-flash at $0.09, also with free output; AWS Strands Labs released the self-hosted Strands Decider 2B. Unbiased released Pareto 26.10 Preview at $0.80 input and $3.20 output. Microsoft released MAI-Transcribe-2-Streaming at $0.54 per audio hour, MAI-Voice-2.1 at $22 per million characters and MAI-Voice-2.1-Flash at $15. Black Forest Labs released FLUX 3 Image at $0.041 to $0.607 per image, and Tavus opened Griffin-Lite as an invite-only research preview with no price. No xAI model launched in October.
- What is the cheapest decision model in October 2026?
- Perplexity pplx-decider-v1-27b, at $0.04 per million input tokens with output free, just under the $0.042 that TypeSafe Jev and Microsoft-Decision-1 charge. Cloudflare Clef-flash costs $0.09 and Clef $0.24 per million input tokens, also with free output. Strands Decider 2B has no hosted rate; you run it on your own hardware.
- Is a decision model cheaper than GPT-6 Luna?
- Only pplx-decider and Jev are clearly cheaper. On a modeled 1,000 decisions at 2,000 input tokens each, pplx-decider costs $0.080 and Jev $0.084, against $0.215 for GPT-6 Luna answering with a short label. Clef-flash costs $0.180, roughly a tie, and Clef costs $0.480, more than a short-label Luna call and about the same as a Luna call with 500 reasoning tokens.
- Did any AI model get cheaper in October 2026?
- Four so far. On October 23 Moonshot launched Kimi K3.1 Pro at $2 and $10 per million tokens, a third below Kimi K3, though Artificial Analysis measures its cost per task level with K3 because it spends more tokens. Unbiased Pareto 26.10 Preview, released October 1, lists at $0.80 input and $3.20 output per million tokens, 68% and 57% below the $2.50 and $7.50 that Pareto 26.9 launched at. On October 6 Google priced Nano Banana 2.1 image output at half the Nano Banana 2 rate, though its input rate tripled. On October 7 Anthropic halved the Claude Sonnet 5.5 cache read to $0.10 per million tokens and launched Claude Haiku 5.5 at a tenth of the Haiku 4.5 price.
- How many AI models has the release archive tracked through October 2026?
- Ninety-seven dated launches from June 9 through October 2026: 5 in June, 21 in July, 12 in August, 34 in September and 25 in October. Every row carries the price the model launched at and a link to the provider primary source.
Sources
OpenAI (2026). GPT-6.1 Terra. OpenAI API model documentation: gpt-6.1-terra $1.00 / $5.00 / $0.05 cached, 1,050,000-token context, knowledge cutoff June 1, 2026. https://developers.openai.com/api/docs/models/gpt-6.1-terra Verified 2026-10-27.
Artificial Analysis (2026). GPT-6.1 Terra model page and GPT-6.1 Terra pushes the cost efficiency frontier. Independent benchmark index: 48 at max effort, $0.40 per index task, 130M output tokens. https://artificialanalysis.ai/models/gpt-6-1-terra and https://artificialanalysis.ai/articles/gpt-6-1-terra-pushes-the-cost-efficiency-frontier Verified 2026-10-27.
Moonshot AI (2026). Kimi K3.1 Pro. Kimi tech blog, October 23, 2026: post-trained K3, Highspeed variant, weights by November 4. https://www.kimi.ai/blog/kimi-k3-1-pro Verified 2026-10-24.
Moonshot AI (2026). Model pricing. Kimi API Platform documentation: kimi-k3.1-pro $2.00 / $10.00 / $0.20 cache hit, kimi-k3 $3.00 / $15.00 / $0.30, K2 series retirement notice. https://platform.kimi.ai/docs/pricing Verified 2026-10-24.
DeepSeek (2026). DeepSeek-V4.1-Flash-1017 Release and Change log. DeepSeek API documentation, October 17, 2026: in-place update behind deepseek-flash, calling method and pricing unchanged. https://api-docs.deepseek.com/news/news261017 and https://api-docs.deepseek.com/updates Verified 2026-10-24.
MiniMax (2026). Pricing overview and Model release notes. MiniMax API documentation: MiniMax-M3.1-Flash at $0.15 / $0.60 / $0.015 cache read, released October 19. https://platform.minimax.io/docs/pricing/overview and https://platform.minimax.io/docs/release-notes/models Verified 2026-10-24.
MiniMax (2026). MiniMax-M3.1-Flash model card and licence. Hugging Face: 428B total and 23B active parameters, community licence terms. https://huggingface.co/MiniMaxAI/MiniMax-M3.1-Flash Verified 2026-10-24.
Artificial Analysis (2026). Kimi K3.1 Pro, DeepSeek V4.1 Flash 1017 and MiniMax-M3.1-Flash model pages. Independent index: 55 ($2.11 per task), 45 at max ($0.26) and 43 ($0.22). https://artificialanalysis.ai/models/kimi-k3-1-pro, https://artificialanalysis.ai/models/deepseek-v4-1-flash-1017 and https://artificialanalysis.ai/models/minimax-m3-1-flash Read 2026-10-24.
TypeSafe AI (2026). Jev: For the builders AND dreamers. Company blog, October 14, 2026: Jev 1.14.0 on jev-preview, experimental images, Box and long context. https://typesafe.ai/blog/jev-1-14 Verified 2026-10-17.
Meta (2026). Muse Spark Open. Meta research blog, October 15, 2026: 816B total and 42B active parameters, 1M-token context, host and download platforms. https://research.meta.ai/blog/muse-spark-open Verified 2026-10-16.
OpenRouter (2026). Meta: Muse Spark Open. Model listing with per-host rates: Modal, Together, Nebius, Fireworks and Baseten at $1.25 input, $0.15 cached input and $4.25 output per million tokens. https://openrouter.ai/meta/muse-spark-open Verified 2026-10-16.
Artificial Analysis (2026). Muse Spark Open model page. Independent index: 39 at xhigh, $0.84 per index task. https://artificialanalysis.ai/models/muse-spark-open Read 2026-10-16.
Cloudflare (2026). Clef: open decision models. Cloudflare blog, October 1, 2026: Apache 2.0, 64K context, vendor-measured median and p95 decision times. https://blog.cloudflare.com/clef-decision-models/ Verified 2026-10-04.
Cloudflare (2026). Clef and Clef-flash. Workers AI model documentation: $0.24 and $0.09 per million input tokens, 65,536-token context. https://developers.cloudflare.com/workers-ai/models/clef/ and https://developers.cloudflare.com/workers-ai/models/clef-flash/ Verified 2026-10-04.
AWS Strands Labs (2026). Introducing Strands Decider 2B: a small, open source, decision model. Strands Agents blog, October 1, 2026. https://strandsagents.com/blog/introducing-strands-decider/ Verified 2026-10-04.
Perplexity (2026). Decisions API. Perplexity API documentation: pplx-decider-v1-27b, $0.04 per million input tokens, output free. https://docs.perplexity.ai/docs/decisions/quickstart Verified 2026-10-04.
Perplexity (2026). pplx-decider-v1-27b. Hugging Face model card: Qwen3.8-27B base, Apache 2.0, vendor benchmark table. https://huggingface.co/perplexity-ai/pplx-decider-v1-27b Verified 2026-10-04.
TypeSafe (2026). Models. TypeSafe documentation: jev-1.13.0 at $0.042 per million input tokens, output free. https://docs.typesafe.ai/models Verified for this site’s Jev post.
OpenAI (2026). API pricing. OpenAI developer documentation, GPT-6 Luna at $0.10 input and $0.50 output per million tokens. https://developers.openai.com/api/docs/pricing Verified 2026-09-23.
Unbiased (2026). Pareto 26.10 Preview model card. Unbiased, October 1, 2026: $0.80 input, $0.03 cached input, $3.20 output per million tokens; preliminary vendor-run benchmarks. https://unbiased.ai/model-card/ Verified 2026-10-04.
Microsoft AI (2026). Our first streaming transcription model debuts at no. 1 on Artificial Analysis. Microsoft AI news, October 1, 2026: MAI-Transcribe-2-Streaming, MAI-Voice-2.1 and MAI-Voice-2.1-Flash, prices and availability. https://microsoft.ai/news/our-first-streaming-transcription-model/ Verified 2026-10-04.
Black Forest Labs (2026). Release notes. BFL documentation, FLUX 3 Image entry dated October 1, 2026, with per-image pricing by resolution. https://docs.bfl.ai/release-notes Verified 2026-10-04.
Tavus (2026). Griffin: The First Human Interaction Model. Tavus, October 1, 2026: Griffin-Lite research preview, VideoFDB scores, company-run human study. https://www.tavus.io/griffin Verified 2026-10-04.
Anthropic (2026). Introducing Claude Haiku 5.5. Anthropic, October 7, 2026: rates by prompt length, the Sonnet 5.5 cache-read cut, vendor-reported benchmarks. https://www.anthropic.com/claude-haiku-5-5 Verified 2026-10-08.
Anthropic (2026). Pricing. Claude Platform documentation: Claude Haiku 5.5 at $0.10/$0.50 up to 100K tokens and $0.50/$2.50 above. https://platform.claude.com/docs/en/about-claude/pricing Verified 2026-10-08.
Mistral AI (2026). Introducing Mistral Large 4. Mistral blog, October 6, 2026. https://mistral.ai/news/mistral-large-4/ Verified 2026-10-08.
Mistral AI (2026). Mistral Large 4. Mistral documentation: 1.05T total and 52B active parameters, 1M context, launch-sale and standard rates. https://docs.mistral.ai/models/mistral-large-4-0 Verified 2026-10-08.
Reflection AI (2026). Introducing Beam: Reflection’s 501B open-weight model. Reflection blog, October 5, 2026. https://reflection.ai/blog/introducing-beam Verified 2026-10-08.
Meta (2026). Introducing Muse Wonder and Muse Wonder Full. Meta Newsroom, October 12, 2026. https://about.fb.com/news/2026/10/introducing-muse-wonder-models/ Verified 2026-10-13.
Meta (2026). Pricing and rate limits and Models. Meta Model API documentation: Muse Wonder at $4, $0.20 cached and $20 per million tokens; Muse Wonder Full in Muse Code only. https://dev.meta.ai/docs/pricing-rate-limits and https://dev.meta.ai/docs/models Verified 2026-10-13.
Artificial Analysis (2026). Muse Wonder model page and Models leaderboard. https://artificialanalysis.ai/models/muse-wonder and https://artificialanalysis.ai/leaderboards/models Read 2026-10-13.
Microsoft (2026). Introducing Microsoft-Decision-1 in Microsoft Foundry for decision and classification. Azure AI Foundry blog, October 9, 2026. https://techcommunity.microsoft.com/blog/azure-ai-foundry-blog/introducing-microsoft-decision-1-in-microsoft-foundry-for-decision-and-classific/4562742 Verified 2026-10-13.
Alibaba Cloud (2026). Qwen-Image-2.1-Turbo. Model Studio documentation, per-image price by region; weights at https://huggingface.co/Qwen/Qwen-Image-2.1-Turbo (repository created 2026-10-09). https://www.alibabacloud.com/help/en/model-studio/qwen-image-2-1-turbo Verified 2026-10-13.
Google (2026). Gemini API release notes. Entry dated October 6, 2026: Gemini Nano Banana 2.1 generally available. https://ai.google.dev/gemini-api/docs/changelog Verified 2026-10-08.
Google (2026). Gemini Developer API pricing. Nano Banana 2.1 and Nano Banana 2 rates; Gemini 4 Argon rates through November 30, 2026 and from December 1. https://ai.google.dev/gemini-api/docs/pricing Verified 2026-10-08; Argon rows checked 2026-10-14.
Google (2026). Gemini 4 Carbon: our next frontier model. Google blog announcement, October 28, 2026: Fairwind-only access, introductory and standard rates. https://blog.google/innovation-and-ai/models-and-research/gemini-models/introducing-gemini-4-carbon/ Verified 2026-10-29.
Artificial Analysis (2026). Gemini 4 Carbon (high). Independent benchmarking service, Intelligence Index v5.0. https://artificialanalysis.ai/models/gemini-4-carbon Read 2026-10-29.
Google (2026). Introducing Gemini 4 Argon. Google blog announcement, October 13, 2026: global availability of Gemini 4 Argon. https://blog.google/innovation-and-ai/models-and-research/gemini-models/introducing-gemini-4-argon/ Verified 2026-10-14.
Artificial Analysis (2026). Claude Haiku 5.5 and Mistral Large 4 Preview model pages. Intelligence Index and cost per task. https://artificialanalysis.ai/models/claude-haiku-5-5 and https://artificialanalysis.ai/models/mistral-large-4 Read 2026-10-08.
Fastino Labs (2026). Introducing GLiDE: The First Thinking Decision Model. Fastino blog, September 30, 2026. https://fastino.ai/blog/introducing-glide-the-first-thinking-decision-model Verified 2026-10-04.
MarkTechPost (2026). Liquid AI Releases d1. Secondary coverage dating Liquid AI’s d1 to September 29, 2026. https://www.marktechpost.com/2026/09/29/liquid-ai-releases-d1-a-decision-model-that-returns-calibrated-probabilities-with-zero-output-tokens/ Read 2026-10-04.
Monthly release counts are derived from the release archive maintained on this site, whose every row carries the provider primary source it was verified against. The cost-per-1,000-decisions figures are this site’s arithmetic on the list prices above.