Mistral Large 4: Pricing, Benchmarks, Open Weights
Mistral Large 4 costs $0.68/$2.09 per million tokens on launch sale, $1.36/$4.18 at list. Artificial Analysis scores it 38. Weights are due by end of October.
Mistral Large 4 is a 1.05-trillion-parameter open-weight model with 52 billion active parameters, in public preview since October 6, 2026 at $0.68 input and $2.09 output per million tokens on a launch sale ($1.36 and $4.18 at list). Weights are due by the end of October.
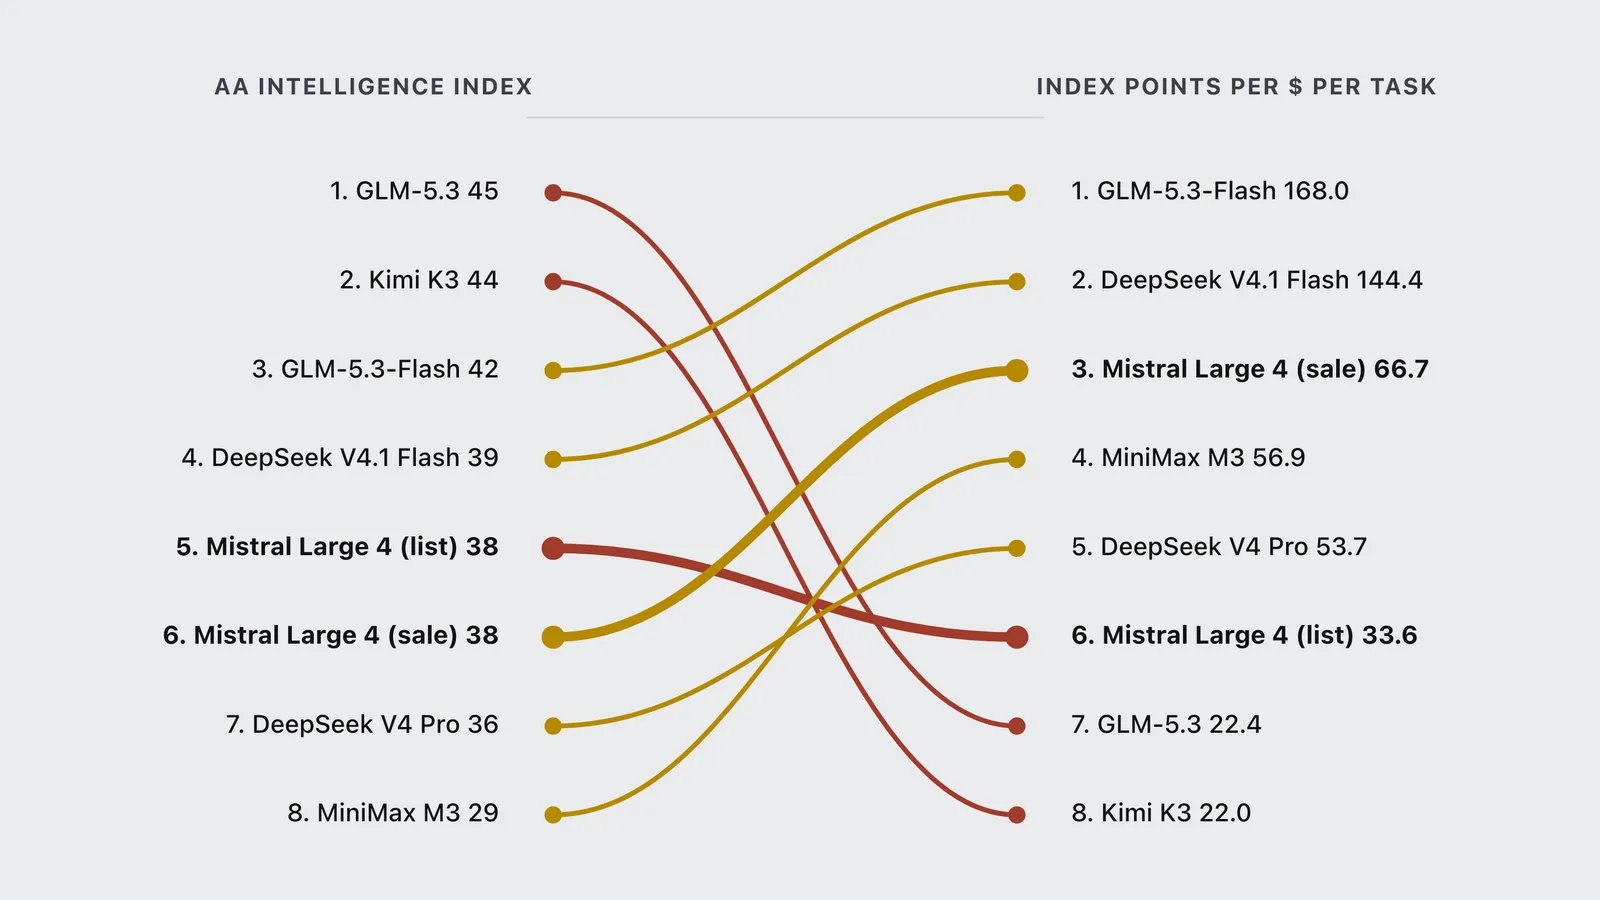
The verdict: Mistral says it beats any open-weight model built in the US or Europe, but it is not the best open-weight model. The independent Artificial Analysis Intelligence Index scores it 38, behind GLM-5.3 (45), Kimi K3 (44), GLM-5.3-Flash (42) and DeepSeek V4.1 Flash (39). All four score higher, and the two Flash models also cost about a quarter as much per task. Buy it for what the index does not weight heavily: cybersecurity work that closed models refuse, European data residency, and image grounding.
| Item | Mistral Large 4 |
|---|---|
| Price today (launch sale) | $0.68 input, $0.07 cached input, $2.09 output per Mtok |
| List price | $1.36 input, $0.14 cached input, $4.18 output per Mtok |
| Sale end date | Not stated by Mistral |
| Availability | Public preview API on Mistral Studio, model mistral-large-4 |
| Open weights | “By the end of the month” (October 2026); licence not yet named |
| Size | 1.05T total, 52B active, granular mixture of experts |
| Context window | 1M tokens |
| Input | Text and images (1.6B-parameter vision encoder) |
| Artificial Analysis Index | 38, ranked #64 of 225 |
| Cost per AA index task | $1.13 at list price |
Prices and the model id are from Mistral’s Mistral Large 4 model documentation, read October 8, 2026. The weights timing is from Mistral’s launch post, Introducing Mistral Large 4 (October 6, 2026).
How much does Mistral Large 4 cost?
At list, $1.36 per million input tokens and $4.18 per million output. Mistral’s documentation shows both numbers struck through and replaced by a sale price of exactly half: $0.68 input, $0.07 for cached input and $2.09 output. The documentation gives no end date for the sale, so treat the list price as the long-run number.
Per token, that puts Large 4 in the middle of the open-weight field. On a blend of three input tokens to one output token, the convention Artificial Analysis uses, list price works out to about $2.07 per million tokens and the sale price to about $1.03. Kimi K3 blends to $6.00 at its $3 and $15 rate. DeepSeek V4.1 Flash blends to about $0.53. These blends are this site’s arithmetic on the published rates.
The rate card is the smaller half of the bill. What a task costs depends on how many tokens the model spends finishing it, and Artificial Analysis measures that directly. Running its full Intelligence Index cost $1,602 for Large 4, an average of $1.13 per task, at list price. Large 4 spent 200 million output tokens on the run.
At the sale price every token costs half, so the same run would come to roughly $0.57 a task. That figure is this site’s arithmetic, assuming every token is billed at the halved rate. It is the number that matters while the sale lasts.
| Model | AA Intelligence Index | Rank by AA Intelligence Index | Index points per $ per task | Rank by index points per dollar |
|---|---|---|---|---|
| GLM-5.3 | 45 | 1 | 22.4 | 7 |
| Kimi K3 | 44 | 2 | 22.0 | 8 |
| GLM-5.3-Flash | 42 | 3 | 168.0 | 1 |
| DeepSeek V4.1 Flash | 39 | 4 | 144.4 | 2 |
| Mistral Large 4 (list) | 38 | 5 | 33.6 | 6 |
| Mistral Large 4 (sale) | 38 | 6 | 66.7 | 3 |
| DeepSeek V4 Pro | 36 | 7 | 53.7 | 5 |
| MiniMax M3 | 29 | 8 | 56.9 | 4 |
The per-task figures behind the chart, all from Artificial Analysis on October 8, 2026: GLM-5.3-Flash $0.25, DeepSeek V4.1 Flash $0.27, MiniMax M3 $0.51, DeepSeek V4 Pro $0.67, Mistral Large 4 $1.13, Kimi K3 $2.00 and GLM-5.3 $2.01. Two closed models sit below all of them: GPT-6 Luna scores 38, level with Large 4, for $0.07 a task, and Claude Haiku 5.5 scores 43 for $0.21.
When can you download the Mistral Large 4 weights?
Mistral’s launch post says the weights will be released “by the end of the month”, which means by the end of October 2026, together with more detail on the architecture, more benchmarks and the post-training method. Until then the only way to run Large 4 is the preview API.
Mistral has not named a licence. Its documentation labels the model “Open” without saying under which terms. Press coverage has filled the gap inconsistently: The Next Web reported a release date of October 27, which Mistral’s own pages do not state. Whether the weights arrive under Apache 2.0, as several earlier Mistral models did, or under a custom licence with commercial limits, is the single biggest open question for anyone planning to self-host. Check the licence file on the day the weights land.
The delay is deliberate. In the launch post Mistral says it is red-teaming the model “in real-world settings with cybersecurity leaders, vetted partners, and state authorities”, who get the same model “with reduced moderation and expanded cyber capabilities”. The public preview is the moderated version.
Self-hosting will not be cheap. At 8 bits per parameter, 1.05 trillion parameters is about 1.05 TB of weights before any context cache, and roughly half that at 4 bits. That is multi-GPU server territory, not a workstation. This is this site’s arithmetic; the local LLM RAM guide walks through the sizing.
Is Mistral Large 4 better than Kimi K3 or GLM-5.3?
On the independent index, no. Artificial Analysis puts Kimi K3 at 44 and GLM-5.3 at 45, six and seven points above Large 4’s 38. Both also cost more per index task, $2.00 and $2.01 against $1.13, so Large 4 is the cheaper of the three to run but the weaker on the same workload. Both rivals are downloadable today: Z.ai published GLM-5.3’s weights on Hugging Face in late August 2026 under its own conditional licence, while Large 4’s weights are still weeks away.
Mistral’s own comparisons point the other way on specific work. All of the following are vendor-reported, from the launch post, and none has been independently reproduced:
- Agentic coding: 61.7% on DeepSWE v1.1, 59.4% on SWE-Atlas-QnA and 28.3% on Terminal-Bench 4. Mistral says its combined Coding Agent Index score of 49.8% puts it ahead of DeepSeek V4 Pro 0813 and Qwen3.8 Max.
- Blind human review: in a Surge AI evaluation where annotators rated coding output from 1 to 5 without seeing model names, Large 4 scored 3.74, ahead of GLM-5.3 (3.60), Kimi K3 (3.59) and GLM-5.2 (3.40), and behind only Claude Opus 5 (4.22).
- Business workflows: 59.9% on AutomationBench, which Mistral describes as 657 workflows across Gmail, Google Sheets, Slack and Salesforce, ahead of Kimi K3 and DeepSeek V4 Pro.
- Image grounding: 42% on Dense 200 against 41% for GPT-6 Astra, a closed frontier model.
Mistral’s in-house expert comparison against GLM-5.3 is more modest: annotators preferred Large 4 for CAD and STEM work and rated it “on par or close” on finance and coding.
How does Mistral Large 4 compare with Reflection Beam?
Mistral’s launch post claims Large 4 is “significantly outperforming any open-weight model developed in the US or Europe”. The independent numbers available today support that. Artificial Analysis scores the American open-weight models it has measured well below 38: Thinking Machines’ Inkling at 25 and NVIDIA’s Nemotron 3 Ultra at 23.
The newest American challenger has no independent score yet. Reflection AI announced Beam on October 5, 2026, one day before Large 4: a 501-billion-parameter model with 23 billion active, text only, with Apache 2.0 weights promised for later in October and early access by waitlist. On the one benchmark both labs report, DeepSWE v1.1, Mistral reports 61.7% for Large 4 and Reflection reports 44.4% for Beam. Both are vendor numbers.
The two models make different bets. Large 4 is the bigger, multimodal generalist, priced and served by Mistral today. Beam is less than half the size, text only, and pitched on efficiency: Reflection says it matches GLM-5.2 on reasoning while using a third to a quarter of the inference compute.
Who is winning the open-weight race in October 2026?
By size and by score, China still leads. Kimi K3, at 2.8 trillion parameters, remains the largest open-weight model available, and all four open-weight models ahead of Large 4 in the chart above are Chinese.
What changed in the first week of October is that two Western labs committed to shipping weights in the same month. Mistral’s Large 4 arrives as the largest European open model, trained on 3,800 NVIDIA Grace Blackwell GPUs in Mistral’s own European data centres and served from the same infrastructure. Reflection’s Beam is the US entry. Both say their training runs had not saturated: Mistral says the reinforcement learning run behind the preview “is still in flight”, and that it expects “large and rapid improvements in the weeks and months to come”. The preview scores are a floor, not a final reading.
The wider field is ranked in the best open-weight AI models of 2026.
Should you use Mistral Large 4?
- Use it for security work. Vulnerability reproduction, malware analysis and detection rules, especially once the weights let you run it without a provider’s refusal policy in the way.
- Use it if data residency is a requirement. Mistral says it operates a European deployment end to end, under European law, independently of other digital service providers.
- Use it for document and image grounding, where Mistral’s own comparison puts it ahead of GPT-6 Astra.
- Do not pick it for cheap, high-volume general work. GLM-5.3-Flash and DeepSeek V4.1 Flash score higher on Artificial Analysis for about a quarter of the per-task cost, and the closed GPT-6 Luna matches its score for $0.07 a task.
- Do not pick it for the strongest open coding model. Kimi K3 scores higher, if you can live with its higher bill.
If the sale ends, the per-task cost doubles back to $1.13 and the value case narrows to the specialist uses above. Current rates for every tracked model are on the AI model tracker, and the value ranking is on the AI model leaderboard. Every other model released this month is in new AI models released in October 2026.
How to get started with Mistral Large 4
- Create a key on Mistral Studio and call the model as
mistral-large-4. The model documentation lists support for chat completions, function calling, structured outputs, document question answering, batching and agents. - Use cached input for repeated context. At $0.07 per million tokens on sale, a cache hit is about a tenth of fresh input.
- Benchmark your own task before committing. The independent index and Mistral’s vertical benchmarks disagree, and only your workload settles which applies to you.
- Plan the self-hosted move for after the weights ship, and read the licence before you do.
Frequently asked questions
- How much does Mistral Large 4 cost?
- Mistral Large 4 lists at $1.36 per million input tokens, $0.14 per million cached input tokens and $4.18 per million output tokens. During its launch it is on sale at exactly half: $0.68 input, $0.07 cached input and $2.09 output. Mistral has not said when the sale ends.
- Is Mistral Large 4 open source?
- It is open-weight, not yet released. Mistral says the weights will be published by the end of October 2026. It has not named the licence, so whether commercial use is unrestricted is not yet known. Until the weights ship, the model is only available through the public preview API.
- How big is Mistral Large 4?
- Mistral documents 1.05 trillion total parameters with 52 billion active per token, in a granular mixture-of-experts design, plus a 1.6-billion-parameter vision encoder. It has a 1-million-token context window and accepts text and images.
- Is Mistral Large 4 better than Kimi K3?
- Not on the independent Artificial Analysis Intelligence Index, where Kimi K3 scores 44 against 38 for Mistral Large 4. Mistral Large 4 is cheaper to run on that index, $1.13 per task at list price against $2.00, and Mistral reports it ahead of Kimi K3 on its own coding and business-workflow tests, which have not been independently reproduced.
- What is Mistral Large 4's Artificial Analysis score?
- Artificial Analysis scores Mistral Large 4 Preview at 38 on its Intelligence Index, ranked 64th of 225 models, read on October 8, 2026. Running the full index cost $1,602, or $1.13 per task, at list price.
Sources
Mistral AI (2026). Introducing Mistral Large 4. Mistral AI blog. https://mistral.ai/news/mistral-large-4/ Verified 2026-10-08.
Mistral AI (2026). Mistral Large 4. Mistral AI documentation, model page and pricing. https://docs.mistral.ai/models/mistral-large-4-0 Verified 2026-10-08.
Artificial Analysis (2026). Mistral Large 4 Preview. Artificial Analysis, independent benchmarking service, Intelligence Index v4.3.2. https://artificialanalysis.ai/models/mistral-large-4 Verified 2026-10-08.
Artificial Analysis (2026). Kimi K3, GLM-5.3, GLM-5.3-Flash, DeepSeek V4.1 Flash, DeepSeek V4 Pro, MiniMax M3, GPT-6 Luna, Claude Haiku 5.5, Inkling and NVIDIA Nemotron 3 Ultra model pages. Artificial Analysis, independent benchmarking service. https://artificialanalysis.ai/models Verified 2026-10-08.
Reflection AI (2026). Introducing Beam: Reflection’s 501B open-weight model. Reflection AI blog. https://reflection.ai/blog/introducing-beam Verified 2026-10-08.
The Next Web (2026). Europe’s Mistral launches Large 4 to challenge China’s lead in open AI models. The Next Web, secondary coverage. https://thenextweb.com/news/mistral-releases-large-4-a-1-trillion-parameter-open-weight-ai-model Verified 2026-10-08.